
#openledger
openledger
17.3M views
202,848 Discussing
Hot
Latest
·
--
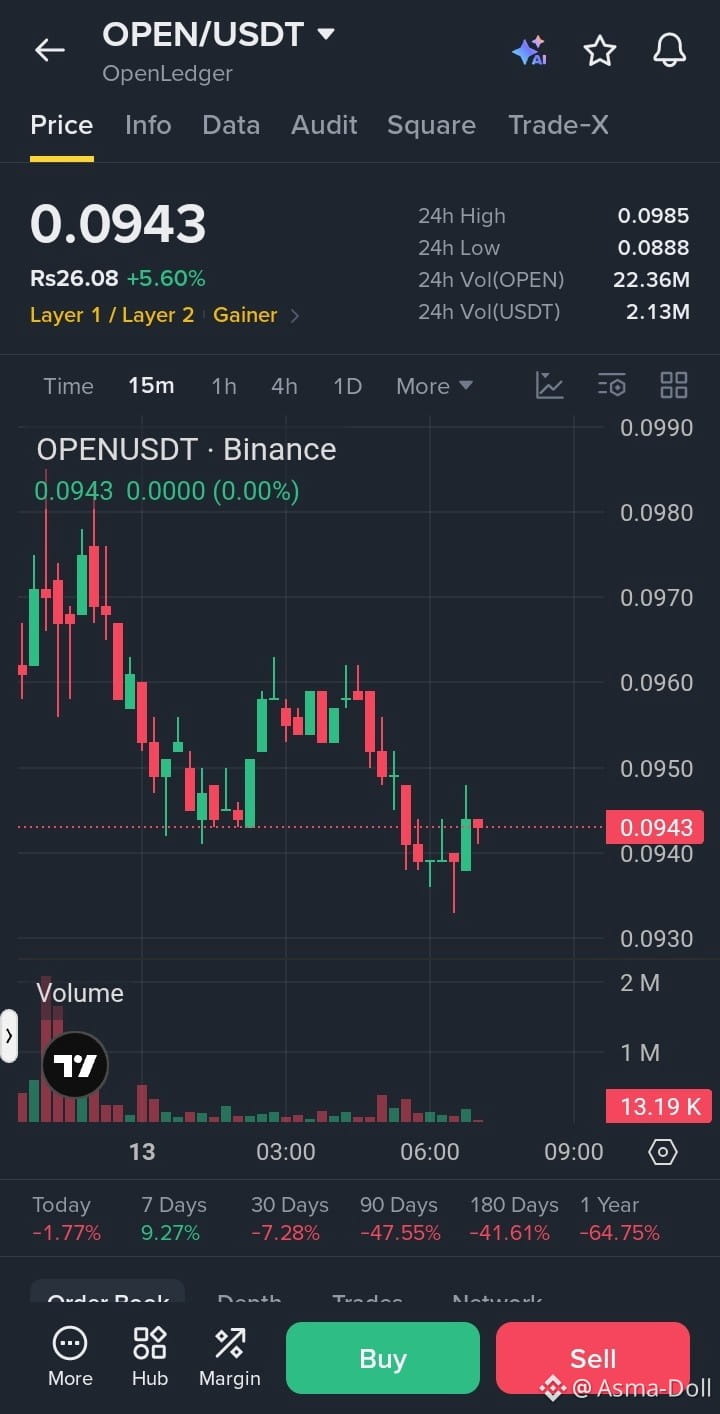
📊 $OPEN /USDT – SHORT SIGNAL
Entry Zone: 0.0945 – 0.0960
Stop Loss (SL): 0.0990
Take Profit Targets:
* TP1: 0.0920
* TP2: 0.0890
* TP3: 0.0850
Trade here $OPEN
{future}(OPENUSDT)
Analysis:
* Price facing rejection near the 0.0985 resistance zone.
* Recent 24h gain of 5.60% indicates a possible short-term pullback.
* 7-day performance remains positive at 9.27%.
* Longer-term trend is weak, with 90-day performance at -47.55%.
* A breakdown below 0.0930 could trigger further downside.
Confirmation:
* Wait for a clean break below 0.0930.
* Prefer a bearish 15m/1h candle with increasing volume.
* Avoid shorting if price breaks and holds above 0.0985.
Risk-to-Reward (approx.): 1:0.6 to TP1, 1:1.3 to TP2, 1:2.2 to TP3 (using 0.0950 entry and 0.0990 SL).
⚠️ Wait for confirmation; this is a speculative setup, not a guaranteed move. Risk only what you can afford to lose.
#OPENUSDT #OPENLedger #CryptoSignals #BinanceFutures #ShortSetup
📊 $OPEN /USDT – SHORT SIGNAL
Entry Zone: 0.0945 – 0.0960
Stop Loss (SL): 0.0990
Take Profit Targets:
* TP1: 0.0920
* TP2: 0.0890
* TP3: 0.0850
Trade here $OPEN
Analysis:
* Price facing rejection near the 0.0985 resistance zone.
* Recent 24h gain of 5.60% indicates a possible short-term pullback.
* 7-day performance remains positive at 9.27%.
* Longer-term trend is weak, with 90-day performance at -47.55%.
* A breakdown below 0.0930 could trigger further downside.
Confirmation:
* Wait for a clean break below 0.0930.
* Prefer a bearish 15m/1h candle with increasing volume.
* Avoid shorting if price breaks and holds above 0.0985.
Risk-to-Reward (approx.): 1:0.6 to TP1, 1:1.3 to TP2, 1:2.2 to TP3 (using 0.0950 entry and 0.0990 SL).
⚠️ Wait for confirmation; this is a speculative setup, not a guaranteed move. Risk only what you can afford to lose.
#OPENUSDT #OPENLedger #CryptoSignals #BinanceFutures #ShortSetup
Entry Zone: 0.0945 – 0.0960
Stop Loss (SL): 0.0990
Take Profit Targets:
* TP1: 0.0920
* TP2: 0.0890
* TP3: 0.0850
Trade here $OPEN
Analysis:
* Price facing rejection near the 0.0985 resistance zone.
* Recent 24h gain of 5.60% indicates a possible short-term pullback.
* 7-day performance remains positive at 9.27%.
* Longer-term trend is weak, with 90-day performance at -47.55%.
* A breakdown below 0.0930 could trigger further downside.
Confirmation:
* Wait for a clean break below 0.0930.
* Prefer a bearish 15m/1h candle with increasing volume.
* Avoid shorting if price breaks and holds above 0.0985.
Risk-to-Reward (approx.): 1:0.6 to TP1, 1:1.3 to TP2, 1:2.2 to TP3 (using 0.0950 entry and 0.0990 SL).
⚠️ Wait for confirmation; this is a speculative setup, not a guaranteed move. Risk only what you can afford to lose.
#OPENUSDT #OPENLedger #CryptoSignals #BinanceFutures #ShortSetup
54
·
--
Bullish
$OPEN is on fire! 🔥
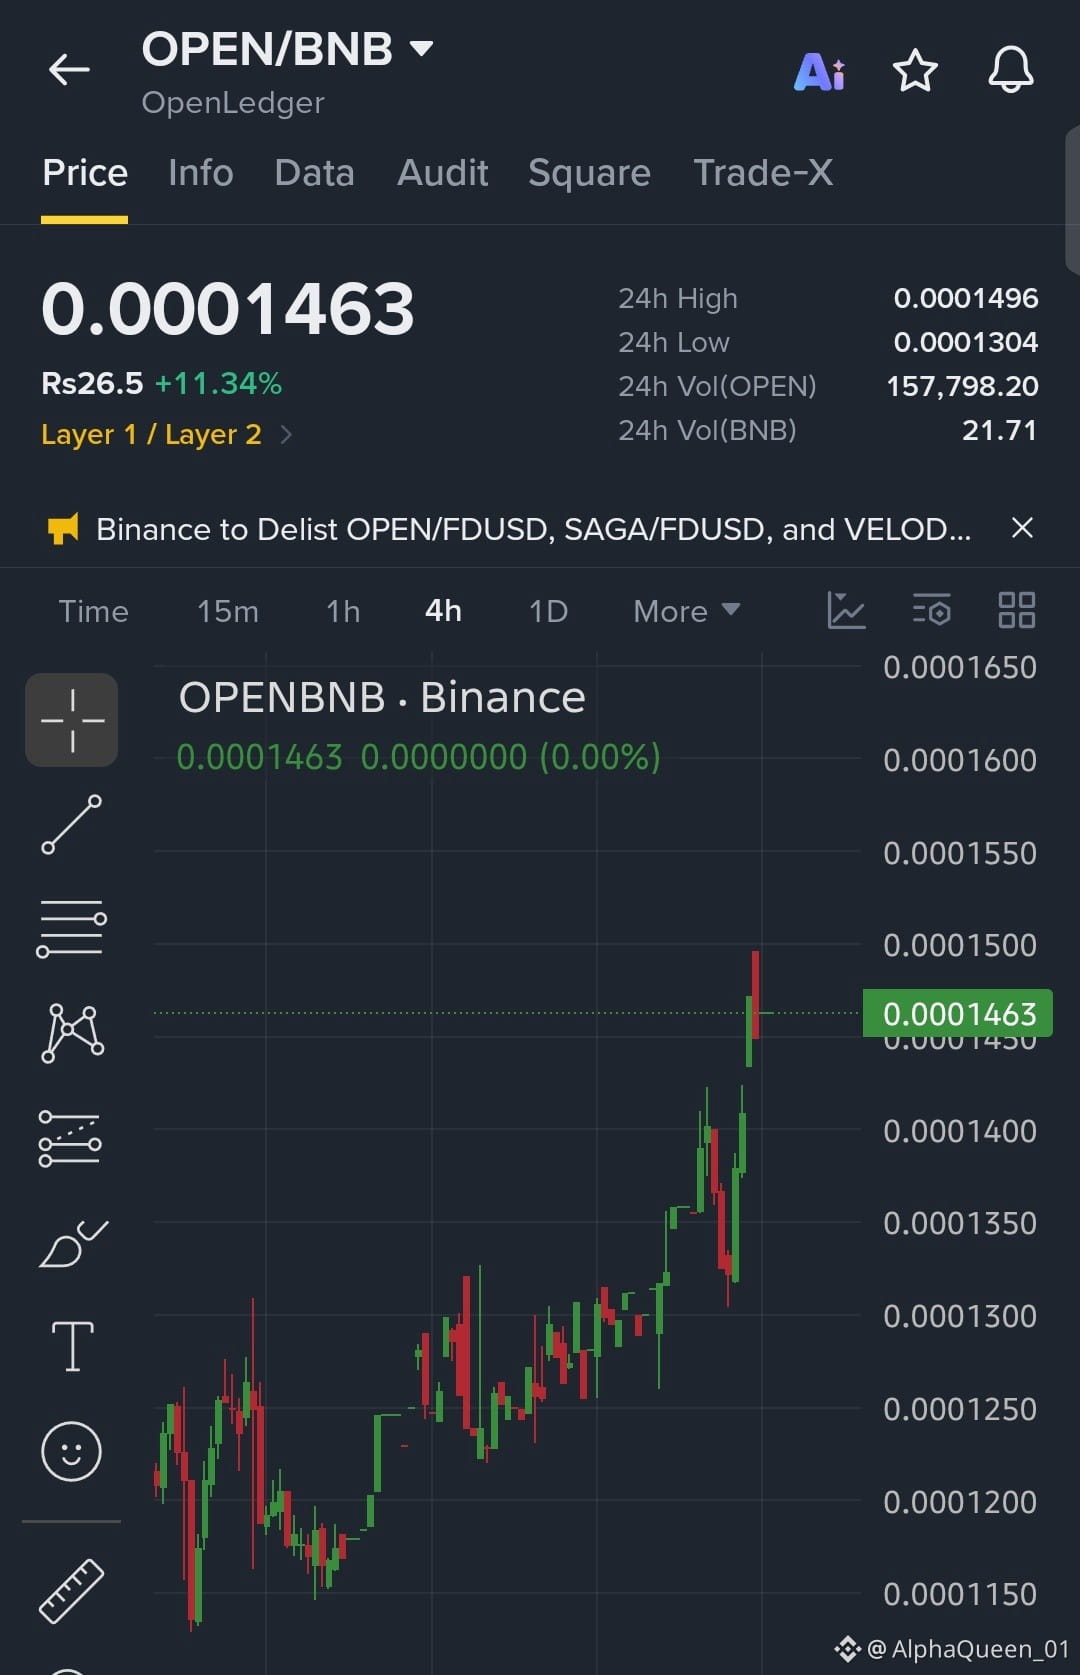
$OPEN /BNB at 0.0001463, up +11.34% today!
From 0.0001304 low to 0.0001496 high - straight pump!
Binance said delist, OPEN said "watch me fly!" 🚀
Who is still holding OPEN? Comment "OPEN ARMY" 👇
#OPEN #OpenLedger #BNB #Crypto
{future}(OPENUSDT)
$OPEN is on fire! 🔥
$OPEN /BNB at 0.0001463, up +11.34% today!
From 0.0001304 low to 0.0001496 high - straight pump!
Binance said delist, OPEN said "watch me fly!" 🚀
Who is still holding OPEN? Comment "OPEN ARMY" 👇
#OPEN #OpenLedger #BNB #Crypto
$OPEN /BNB at 0.0001463, up +11.34% today!
From 0.0001304 low to 0.0001496 high - straight pump!
Binance said delist, OPEN said "watch me fly!" 🚀
Who is still holding OPEN? Comment "OPEN ARMY" 👇
#OPEN #OpenLedger #BNB #Crypto
6
277
·
--
$币安人生 The crypto market is telling an interesting story today! 🔥 Bitcoin is trading around $71,486.9, down 3.33%, while ($BTC )(Binance Life) has slipped 5.47% to $0.4719. But OpenLedger (OPEN) is showing a different direction, holding at $0.0971 with a 0.83% gain.
What makes OpenLedger interesting is its ability to attract attention even when broader market sentiment is under pressure. While traders are watching Bitcoin's next move, $OPEN is raising an important question: could this project develop stronger momentum while the market searches for stability?
Is OpenLedger building something that can stand out beyond short-term price movements? Can OPEN maintain its strength if Bitcoin continues facing selling pressure? And what could become the next major catalyst for its ecosystem?
The next chapter is still being written. Keep watching the fundamentals, adoption, and market activity rather than judging the project by one green candle.
Is OPEN preparing for a bigger opportunity, or is this just a temporary market bounce? 👀
{future}(币安人生USDT)
{future}(OPENUSDT)
{future}(BTCUSDT)
#OpenLedger #OPENUSDT #CryptoMarket
$币安人生 The crypto market is telling an interesting story today! 🔥 Bitcoin is trading around $71,486.9, down 3.33%, while ($BTC )(Binance Life) has slipped 5.47% to $0.4719. But OpenLedger (OPEN) is showing a different direction, holding at $0.0971 with a 0.83% gain.
What makes OpenLedger interesting is its ability to attract attention even when broader market sentiment is under pressure. While traders are watching Bitcoin's next move, $OPEN is raising an important question: could this project develop stronger momentum while the market searches for stability?
Is OpenLedger building something that can stand out beyond short-term price movements? Can OPEN maintain its strength if Bitcoin continues facing selling pressure? And what could become the next major catalyst for its ecosystem?
The next chapter is still being written. Keep watching the fundamentals, adoption, and market activity rather than judging the project by one green candle.
Is OPEN preparing for a bigger opportunity, or is this just a temporary market bounce? 👀
#OpenLedger #OPENUSDT #CryptoMarket
What makes OpenLedger interesting is its ability to attract attention even when broader market sentiment is under pressure. While traders are watching Bitcoin's next move, $OPEN is raising an important question: could this project develop stronger momentum while the market searches for stability?
Is OpenLedger building something that can stand out beyond short-term price movements? Can OPEN maintain its strength if Bitcoin continues facing selling pressure? And what could become the next major catalyst for its ecosystem?
The next chapter is still being written. Keep watching the fundamentals, adoption, and market activity rather than judging the project by one green candle.
Is OPEN preparing for a bigger opportunity, or is this just a temporary market bounce? 👀
#OpenLedger #OPENUSDT #CryptoMarket
$币安人生 🔙👍✅
64%
$BTC 💻📞📱
18%
$OPEN 😀😁😂
18%
11 votes • Voting closed
1
3k
·
--
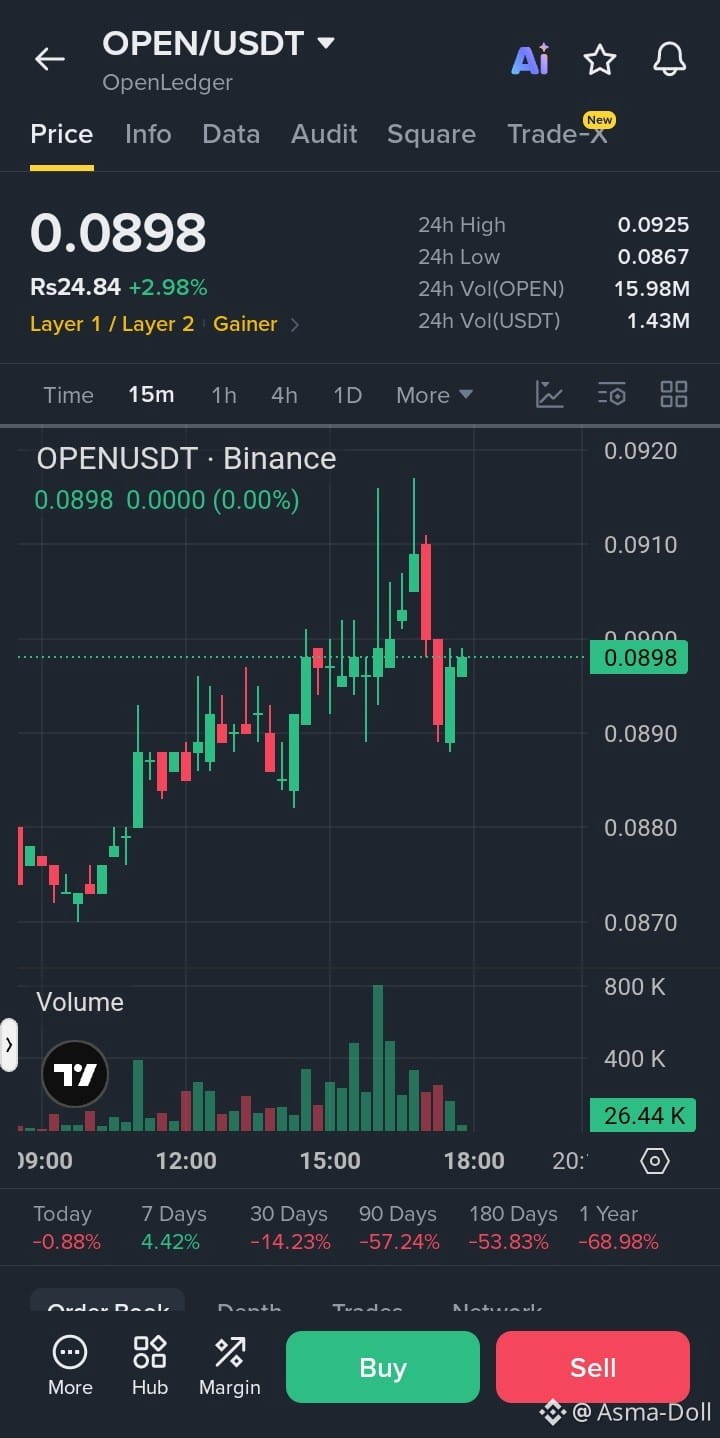
🔴 $OPEN /USDT – SHORT SIGNAL OpenLedger | Bearish Setup
Entry Zone: 0.0895 – 0.0905
Stop Loss (SL): 0.0930
🎯 Take Profit (TP):
TP1: 0.0875
TP2: 0.0855
TP3: 0.0820
Trade here $OPEN
{future}(OPENUSDT)
Analysis:
Price facing rejection near 0.0925 resistance.
30-day performance is down 14.23%.
90-day performance shows a massive 57.24% decline.
1-year trend remains strongly bearish.
Short-term bounce may face selling pressure.
Buyers need strong volume to reverse the trend.
Confirmation: A clean break below 0.0880 with strong selling volume could trigger further downside.
Risk-to-Reward: Approximately 1:1 to 1:2.1, depending on entry and target.
⚠️ Wait for bearish confirmation before entering. These levels are indicative, not guaranteed.
#OPENUSDT #OpenLedger #CryptoSignals #BinanceFutures #ShortSignal
🔴 $OPEN /USDT – SHORT SIGNAL OpenLedger | Bearish Setup
Entry Zone: 0.0895 – 0.0905
Stop Loss (SL): 0.0930
🎯 Take Profit (TP):
TP1: 0.0875
TP2: 0.0855
TP3: 0.0820
Trade here $OPEN
Analysis:
Price facing rejection near 0.0925 resistance.
30-day performance is down 14.23%.
90-day performance shows a massive 57.24% decline.
1-year trend remains strongly bearish.
Short-term bounce may face selling pressure.
Buyers need strong volume to reverse the trend.
Confirmation: A clean break below 0.0880 with strong selling volume could trigger further downside.
Risk-to-Reward: Approximately 1:1 to 1:2.1, depending on entry and target.
⚠️ Wait for bearish confirmation before entering. These levels are indicative, not guaranteed.
#OPENUSDT #OpenLedger #CryptoSignals #BinanceFutures #ShortSignal
Entry Zone: 0.0895 – 0.0905
Stop Loss (SL): 0.0930
🎯 Take Profit (TP):
TP1: 0.0875
TP2: 0.0855
TP3: 0.0820
Trade here $OPEN
Analysis:
Price facing rejection near 0.0925 resistance.
30-day performance is down 14.23%.
90-day performance shows a massive 57.24% decline.
1-year trend remains strongly bearish.
Short-term bounce may face selling pressure.
Buyers need strong volume to reverse the trend.
Confirmation: A clean break below 0.0880 with strong selling volume could trigger further downside.
Risk-to-Reward: Approximately 1:1 to 1:2.1, depending on entry and target.
⚠️ Wait for bearish confirmation before entering. These levels are indicative, not guaranteed.
#OPENUSDT #OpenLedger #CryptoSignals #BinanceFutures #ShortSignal
24
·
--
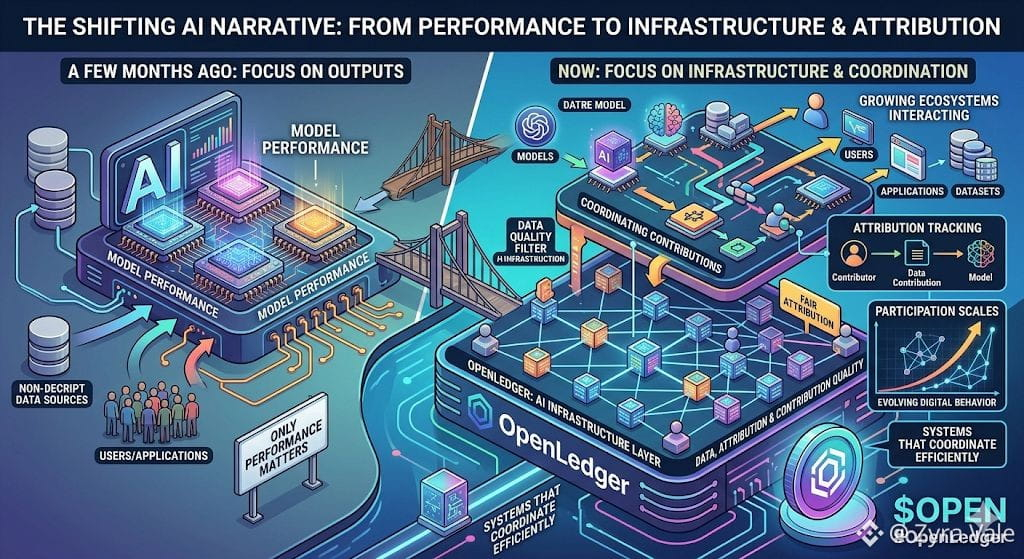
Feels like the AI narrative is slowly shifting lately.
a few months ago most people only cared about model performance.
now I’m noticing more discussions around data, attribution, and contribution quality too.
that’s partly why OpenLedger started standing out to me recently.
the project feels focused on a layer of AI infrastructure that probably becomes more important as ecosystems grow.
especially once more users, applications, and datasets start interacting across networks.
crypto already showed how fast digital behavior evolves once participation scales.
so systems that can coordinate contributions and attribution more efficiently could end up becoming a pretty important part of the AI ecosystem later on.
still early obviously.
but feels like the market is gradually starting to pay more attention to the infrastructure underneath AI instead of only the outputs.
that’s mainly why I’ve been watching $OPEN lately.
#openledger $OPEN @Openledger
Feels like the AI narrative is slowly shifting lately.
a few months ago most people only cared about model performance.
now I’m noticing more discussions around data, attribution, and contribution quality too.
that’s partly why OpenLedger started standing out to me recently.
the project feels focused on a layer of AI infrastructure that probably becomes more important as ecosystems grow.
especially once more users, applications, and datasets start interacting across networks.
crypto already showed how fast digital behavior evolves once participation scales.
so systems that can coordinate contributions and attribution more efficiently could end up becoming a pretty important part of the AI ecosystem later on.
still early obviously.
but feels like the market is gradually starting to pay more attention to the infrastructure underneath AI instead of only the outputs.
that’s mainly why I’ve been watching $OPEN lately.
#openledger $OPEN @OpenLedger
a few months ago most people only cared about model performance.
now I’m noticing more discussions around data, attribution, and contribution quality too.
that’s partly why OpenLedger started standing out to me recently.
the project feels focused on a layer of AI infrastructure that probably becomes more important as ecosystems grow.
especially once more users, applications, and datasets start interacting across networks.
crypto already showed how fast digital behavior evolves once participation scales.
so systems that can coordinate contributions and attribution more efficiently could end up becoming a pretty important part of the AI ecosystem later on.
still early obviously.
but feels like the market is gradually starting to pay more attention to the infrastructure underneath AI instead of only the outputs.
that’s mainly why I’ve been watching $OPEN lately.
#openledger $OPEN @OpenLedger
2
186
·
--
I've recently been designing an automated process for multi-Agent collaboration, and the more I work on it, the more I feel that the vision of @Openledger "thousands of Agents automatically calling and settling with each other" sounds sexy. However, when it comes to implementation, there's a critical engineering risk hidden: cascading failures.
Let me share my real-world scenario. I have three microservices: A is responsible for fetching on-chain data, B cleans that data into structured reports, and C makes decisions based on those reports. In a centralized system, I can add timeouts, retries, and circuit breakers at each stage. If A goes down, C can immediately sense it and downgrade, preventing it from running with dirty data. This fault tolerance mechanism took me quite a while to stabilize locally.
Now, moving this setup to OpenLedger's decentralized network makes the difficulty go off the charts. When Agent C automatically purchases reports from Agent B and B automatically pays A for data fees, the entire call chain is fully automated and unattended. Here's the problem: if a node on A's side suddenly loses power, goes offline, or crashes, how does the fault propagate through the chain?
The worst-case scenario is that A doesn't completely crash but returns "seemingly normal, but actually dirty data". B won't question it; it will accept it as is and clean it into a report, and C will execute a transaction with real funds on-chain based on this report with dirty data without hesitation. By the time you realize something's wrong, the losses have already occurred, and because it's fully automated, no one can hit the pause button in time. $LAB
In a centralized system, I can monitor the market, block, or roll back at any time. But in a fully automated, black-box decentralized network, no one can perform "surgery" on that fast-moving chain. Even if the system later compensates by slashing A's deposit through a smart contract, my business would already have faced catastrophic downtime due to this cascading failure.
So, objectively speaking, OpenLedger's direction toward Agent composability is correct; it indeed hits the trend of machine economy. But "losing data can cost money" is far from enough; serious commercial use demands that "the chain cannot be wrong for even a second". Don't just focus on the coolness of automated settlement; analyze its real design in fault tolerance and cascading failure prevention, stay neutral, and DYOR. #BTC
#OpenLedger $OPEN @Openledger
{future}(LABUSDT)
{spot}(OPENUSDT)
I've recently been designing an automated process for multi-Agent collaboration, and the more I work on it, the more I feel that the vision of @OpenLedger "thousands of Agents automatically calling and settling with each other" sounds sexy. However, when it comes to implementation, there's a critical engineering risk hidden: cascading failures.
Let me share my real-world scenario. I have three microservices: A is responsible for fetching on-chain data, B cleans that data into structured reports, and C makes decisions based on those reports. In a centralized system, I can add timeouts, retries, and circuit breakers at each stage. If A goes down, C can immediately sense it and downgrade, preventing it from running with dirty data. This fault tolerance mechanism took me quite a while to stabilize locally.
Now, moving this setup to OpenLedger's decentralized network makes the difficulty go off the charts. When Agent C automatically purchases reports from Agent B and B automatically pays A for data fees, the entire call chain is fully automated and unattended. Here's the problem: if a node on A's side suddenly loses power, goes offline, or crashes, how does the fault propagate through the chain?
The worst-case scenario is that A doesn't completely crash but returns "seemingly normal, but actually dirty data". B won't question it; it will accept it as is and clean it into a report, and C will execute a transaction with real funds on-chain based on this report with dirty data without hesitation. By the time you realize something's wrong, the losses have already occurred, and because it's fully automated, no one can hit the pause button in time. $LAB
In a centralized system, I can monitor the market, block, or roll back at any time. But in a fully automated, black-box decentralized network, no one can perform "surgery" on that fast-moving chain. Even if the system later compensates by slashing A's deposit through a smart contract, my business would already have faced catastrophic downtime due to this cascading failure.
So, objectively speaking, OpenLedger's direction toward Agent composability is correct; it indeed hits the trend of machine economy. But "losing data can cost money" is far from enough; serious commercial use demands that "the chain cannot be wrong for even a second". Don't just focus on the coolness of automated settlement; analyze its real design in fault tolerance and cascading failure prevention, stay neutral, and DYOR. #BTC
#OpenLedger $OPEN @OpenLedger
Let me share my real-world scenario. I have three microservices: A is responsible for fetching on-chain data, B cleans that data into structured reports, and C makes decisions based on those reports. In a centralized system, I can add timeouts, retries, and circuit breakers at each stage. If A goes down, C can immediately sense it and downgrade, preventing it from running with dirty data. This fault tolerance mechanism took me quite a while to stabilize locally.
Now, moving this setup to OpenLedger's decentralized network makes the difficulty go off the charts. When Agent C automatically purchases reports from Agent B and B automatically pays A for data fees, the entire call chain is fully automated and unattended. Here's the problem: if a node on A's side suddenly loses power, goes offline, or crashes, how does the fault propagate through the chain?
The worst-case scenario is that A doesn't completely crash but returns "seemingly normal, but actually dirty data". B won't question it; it will accept it as is and clean it into a report, and C will execute a transaction with real funds on-chain based on this report with dirty data without hesitation. By the time you realize something's wrong, the losses have already occurred, and because it's fully automated, no one can hit the pause button in time. $LAB
In a centralized system, I can monitor the market, block, or roll back at any time. But in a fully automated, black-box decentralized network, no one can perform "surgery" on that fast-moving chain. Even if the system later compensates by slashing A's deposit through a smart contract, my business would already have faced catastrophic downtime due to this cascading failure.
So, objectively speaking, OpenLedger's direction toward Agent composability is correct; it indeed hits the trend of machine economy. But "losing data can cost money" is far from enough; serious commercial use demands that "the chain cannot be wrong for even a second". Don't just focus on the coolness of automated settlement; analyze its real design in fault tolerance and cascading failure prevention, stay neutral, and DYOR. #BTC
#OpenLedger $OPEN @OpenLedger
自动调用链断了怎么办
50%
Agent 协作扛得住故障吗
50%
2 votes • Voting closed
2
1
455
·
--
The Value Flywheel of OpenLedgerWhen assessing the long-term viability of a Decentralized Physical Infrastructure Network (DePIN), the tokenomics model must be robust enough to sustain physical hardware contributions. A project cannot rely on hype alone; it requires a self-sustaining loop. This is precisely why the economic blueprint of @Openledger is garnering significant developer interest.
The relationship between the network and its native asset, the $OPEN token, is built on hard utility. As decentralized applications and enterprises tap into the network for secure data storage and verifiable compute, they actively utilize $OPEN to settle transaction costs and secure operational bandwidth. This continuous demand rewards the node providers who keep the infrastructure secure, forming a healthy growth loop. As global data creation continues to grow exponentially, establishing a decentralized market for processing that data positions this protocol at the absolute forefront of Web3 innovation. #OpenLedger
The Value Flywheel of OpenLedger
When assessing the long-term viability of a Decentralized Physical Infrastructure Network (DePIN), the tokenomics model must be robust enough to sustain physical hardware contributions. A project cannot rely on hype alone; it requires a self-sustaining loop. This is precisely why the economic blueprint of @OpenLedger is garnering significant developer interest.
The relationship between the network and its native asset, the $OPEN token, is built on hard utility. As decentralized applications and enterprises tap into the network for secure data storage and verifiable compute, they actively utilize $OPEN to settle transaction costs and secure operational bandwidth. This continuous demand rewards the node providers who keep the infrastructure secure, forming a healthy growth loop. As global data creation continues to grow exponentially, establishing a decentralized market for processing that data positions this protocol at the absolute forefront of Web3 innovation. #OpenLedger
The relationship between the network and its native asset, the $OPEN token, is built on hard utility. As decentralized applications and enterprises tap into the network for secure data storage and verifiable compute, they actively utilize $OPEN to settle transaction costs and secure operational bandwidth. This continuous demand rewards the node providers who keep the infrastructure secure, forming a healthy growth loop. As global data creation continues to grow exponentially, establishing a decentralized market for processing that data positions this protocol at the absolute forefront of Web3 innovation. #OpenLedger
1
88
·
--
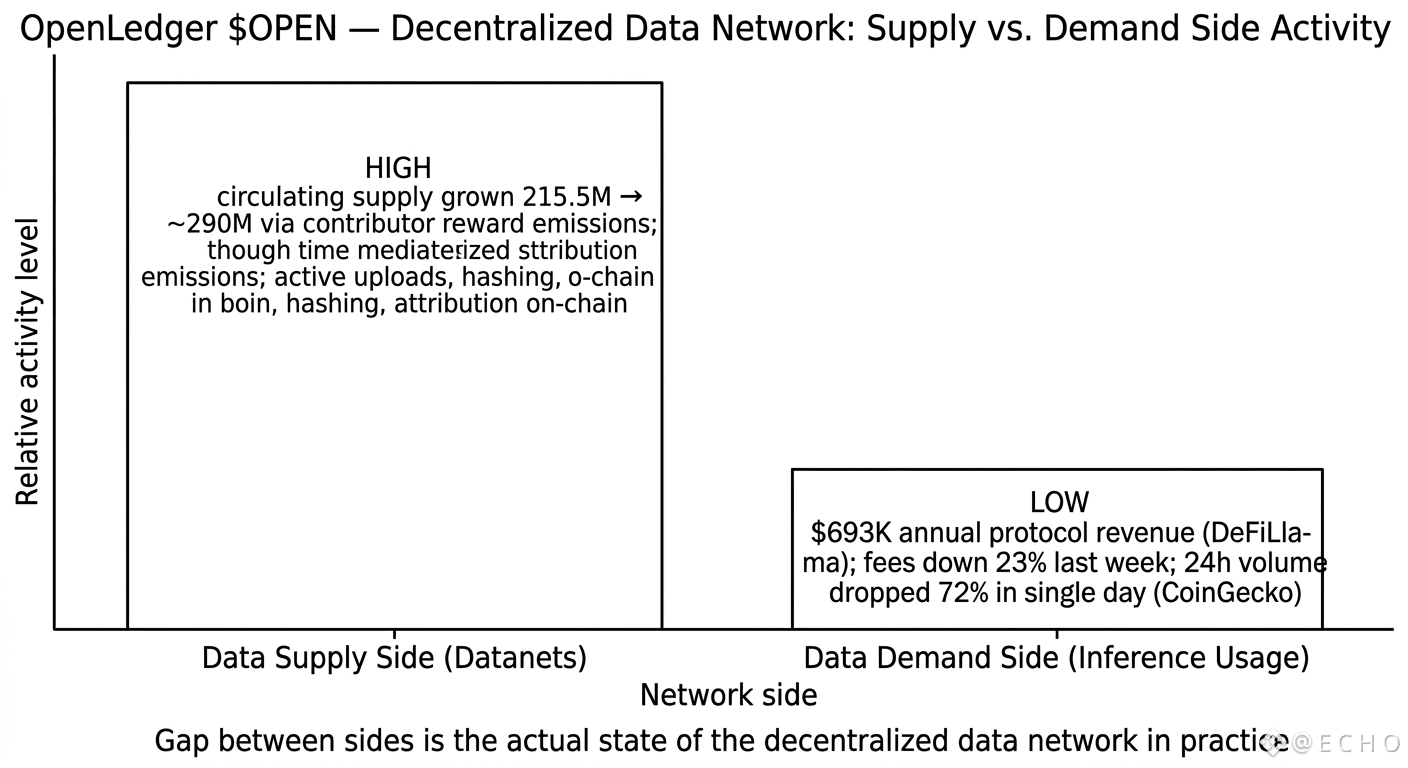
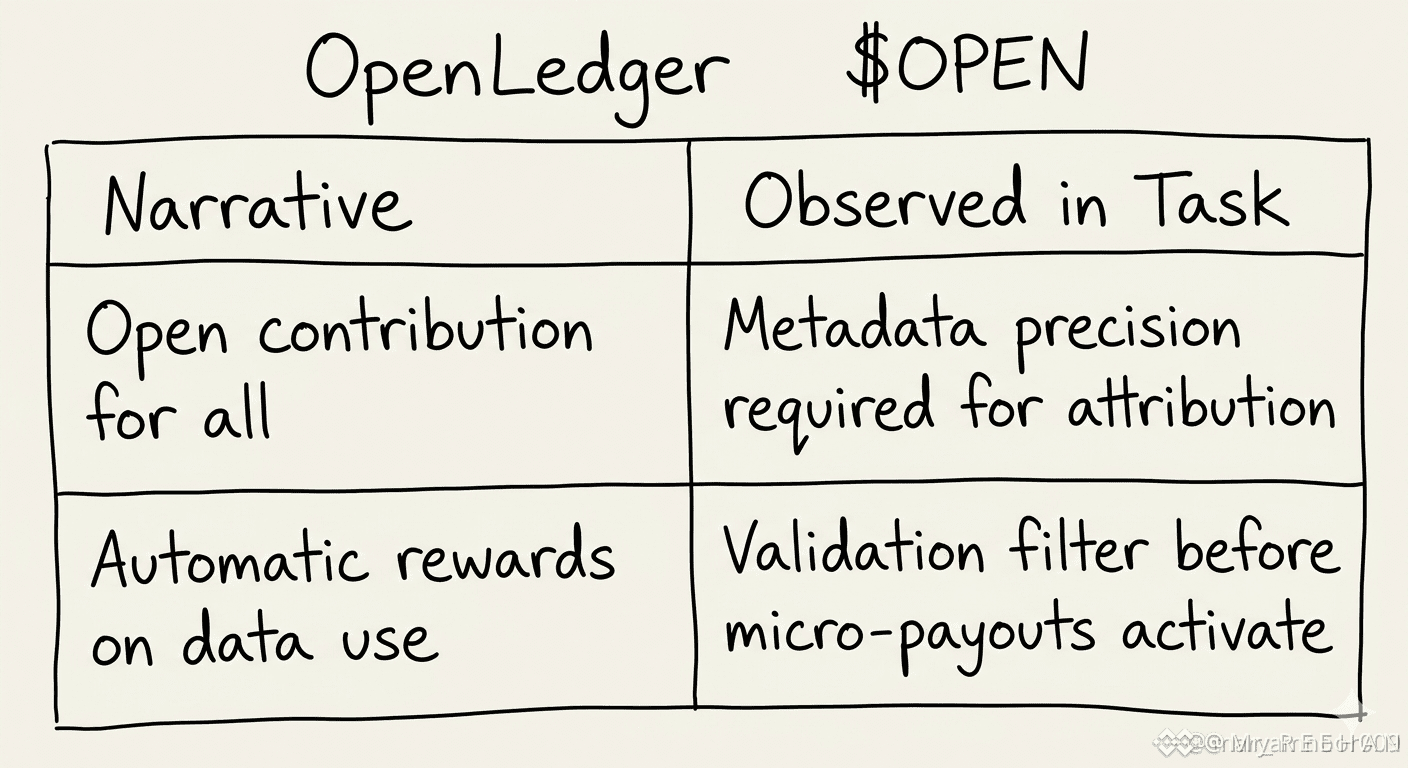
What caught me during the OpenLedger $OPEN #OpenLedger @Openledger task wasn't the infrastructure — it's genuinely interesting — it was noticing which half of the data network is actually running. Datanets are growing. Contributors are uploading, tagging, hashing. The supply side of the decentralized data story is active and getting rewarded via token emissions — circulating supply has expanded from 215.5M to roughly 290M OPEN since TGE, per CoinMarketCap. That growth is real and it shows people showing up.
The demand side is a different picture. DeFiLlama pegs annual protocol revenue at $693K, with fees down 23% in the past week. And CoinGecko shows 24-hour trading volume fell 72% in a single day recently, which is volatile even by crypto standards. The Datanets exist, the data sits there attributed and hashed, but the inference demand that was supposed to flow through and compensate contributors proportionally… hasn't arrived at scale yet.
I kept thinking about Ocean Protocol's early years. Same shape of problem — rich on supply infrastructure, waiting on demand. The question OpenLedger hasn't answered yet isn't whether decentralized data networks matter. It's what actually pulls builders to query these specific Datanets over cheaper, faster, centralized alternatives.
What caught me during the OpenLedger $OPEN #OpenLedger @OpenLedger task wasn't the infrastructure — it's genuinely interesting — it was noticing which half of the data network is actually running. Datanets are growing. Contributors are uploading, tagging, hashing. The supply side of the decentralized data story is active and getting rewarded via token emissions — circulating supply has expanded from 215.5M to roughly 290M OPEN since TGE, per CoinMarketCap. That growth is real and it shows people showing up.
The demand side is a different picture. DeFiLlama pegs annual protocol revenue at $693K, with fees down 23% in the past week. And CoinGecko shows 24-hour trading volume fell 72% in a single day recently, which is volatile even by crypto standards. The Datanets exist, the data sits there attributed and hashed, but the inference demand that was supposed to flow through and compensate contributors proportionally… hasn't arrived at scale yet.
I kept thinking about Ocean Protocol's early years. Same shape of problem — rich on supply infrastructure, waiting on demand. The question OpenLedger hasn't answered yet isn't whether decentralized data networks matter. It's what actually pulls builders to query these specific Datanets over cheaper, faster, centralized alternatives.
The demand side is a different picture. DeFiLlama pegs annual protocol revenue at $693K, with fees down 23% in the past week. And CoinGecko shows 24-hour trading volume fell 72% in a single day recently, which is volatile even by crypto standards. The Datanets exist, the data sits there attributed and hashed, but the inference demand that was supposed to flow through and compensate contributors proportionally… hasn't arrived at scale yet.
I kept thinking about Ocean Protocol's early years. Same shape of problem — rich on supply infrastructure, waiting on demand. The question OpenLedger hasn't answered yet isn't whether decentralized data networks matter. It's what actually pulls builders to query these specific Datanets over cheaper, faster, centralized alternatives.
1
416
OPENLEDGER: MAYBE THE FUTURE IS NOT ONE GIANT AI KINGI think the AI world has a strange obsession with size. Bigger model, bigger compute, bigger benchmark, bigger announcement. Everyone wants to build the giant brain that knows everything. Sounds powerful, yes… but also a little funny, because half the time that giant brain still gets a simple niche question wrong with full confidence.
That is why I keep looking at OpenLedger from a different angle. Maybe the interesting part is not one massive AI model ruling everything. Maybe the better story is many smaller, focused models that actually know their own job properly. Not one king sitting on top of all knowledge. More like model farmers growing useful models from specific data.
This is where Datanets, Model Factory, and OpenLoRA start connecting in my head. Datanets can be the soil. The focused data. The thing that gives a model its actual knowledge. Model Factory becomes the place where that data can be turned into something usable. Then OpenLoRA makes the model side lighter and more practical, especially for specialized use cases. Not every task needs a giant model with a huge ego and a bigger server bill.
Think about DeFi risk, legal data, trading signals, gaming, creator IP, medical research, or on-chain analytics. These areas do not always need a general model trying to act like it read the whole internet before breakfast. They need focused models trained on cleaner, more relevant data. A smaller model with the right knowledge can be more useful than a huge model guessing beautifully.
And this is where OpenLedger’s attribution idea becomes important too. If smaller models are built from specific Datanets, then the value chain becomes easier to understand. Which data helped? Which contributor mattered? Which model improved the output? Who should get credit if the model becomes useful? That is much cleaner than throwing everything into one giant black box and calling it intelligence.
I also like this theme because it feels less like hype and more like infrastructure. Giant models are impressive, but they are expensive, heavy, and not always practical. Specialized models feel more like tools. One model for one job. Another model for another job. Many focused brains instead of one oversized brain pretending to be perfect.
Of course, this is not automatically easy. Small models still need good data. Datanets need quality control. Builders need real reasons to use Model Factory. OpenLoRA needs actual adoption. Otherwise, the whole thing stays as a nice idea on paper, and crypto already has enough nice ideas living permanently on paper.
But the direction makes sense to me. AI does not have to be only a race for the biggest model. It can also be a race for the most useful model. The cleanest data. The best attribution. The easiest deployment. The strongest niche performance.
That is why I think OpenLedger’s model story is underrated. People may focus on agents first because agents are more visible. But agents need models. Models need data. Data needs attribution. And if OpenLedger can make that loop work, then the real win may come from many small, useful models growing inside the ecosystem.
Not model kings.
Model farmers.
Less dramatic maybe… but probably more useful.
@Openledger #OpenLedger $OPEN
$LAB
OPENLEDGER: MAYBE THE FUTURE IS NOT ONE GIANT AI KING
I think the AI world has a strange obsession with size. Bigger model, bigger compute, bigger benchmark, bigger announcement. Everyone wants to build the giant brain that knows everything. Sounds powerful, yes… but also a little funny, because half the time that giant brain still gets a simple niche question wrong with full confidence.
That is why I keep looking at OpenLedger from a different angle. Maybe the interesting part is not one massive AI model ruling everything. Maybe the better story is many smaller, focused models that actually know their own job properly. Not one king sitting on top of all knowledge. More like model farmers growing useful models from specific data.
This is where Datanets, Model Factory, and OpenLoRA start connecting in my head. Datanets can be the soil. The focused data. The thing that gives a model its actual knowledge. Model Factory becomes the place where that data can be turned into something usable. Then OpenLoRA makes the model side lighter and more practical, especially for specialized use cases. Not every task needs a giant model with a huge ego and a bigger server bill.
Think about DeFi risk, legal data, trading signals, gaming, creator IP, medical research, or on-chain analytics. These areas do not always need a general model trying to act like it read the whole internet before breakfast. They need focused models trained on cleaner, more relevant data. A smaller model with the right knowledge can be more useful than a huge model guessing beautifully.
And this is where OpenLedger’s attribution idea becomes important too. If smaller models are built from specific Datanets, then the value chain becomes easier to understand. Which data helped? Which contributor mattered? Which model improved the output? Who should get credit if the model becomes useful? That is much cleaner than throwing everything into one giant black box and calling it intelligence.
I also like this theme because it feels less like hype and more like infrastructure. Giant models are impressive, but they are expensive, heavy, and not always practical. Specialized models feel more like tools. One model for one job. Another model for another job. Many focused brains instead of one oversized brain pretending to be perfect.
Of course, this is not automatically easy. Small models still need good data. Datanets need quality control. Builders need real reasons to use Model Factory. OpenLoRA needs actual adoption. Otherwise, the whole thing stays as a nice idea on paper, and crypto already has enough nice ideas living permanently on paper.
But the direction makes sense to me. AI does not have to be only a race for the biggest model. It can also be a race for the most useful model. The cleanest data. The best attribution. The easiest deployment. The strongest niche performance.
That is why I think OpenLedger’s model story is underrated. People may focus on agents first because agents are more visible. But agents need models. Models need data. Data needs attribution. And if OpenLedger can make that loop work, then the real win may come from many small, useful models growing inside the ecosystem.
Not model kings.
Model farmers.
Less dramatic maybe… but probably more useful.
@OpenLedger #OpenLedger $OPEN
$LAB
That is why I keep looking at OpenLedger from a different angle. Maybe the interesting part is not one massive AI model ruling everything. Maybe the better story is many smaller, focused models that actually know their own job properly. Not one king sitting on top of all knowledge. More like model farmers growing useful models from specific data.
This is where Datanets, Model Factory, and OpenLoRA start connecting in my head. Datanets can be the soil. The focused data. The thing that gives a model its actual knowledge. Model Factory becomes the place where that data can be turned into something usable. Then OpenLoRA makes the model side lighter and more practical, especially for specialized use cases. Not every task needs a giant model with a huge ego and a bigger server bill.
Think about DeFi risk, legal data, trading signals, gaming, creator IP, medical research, or on-chain analytics. These areas do not always need a general model trying to act like it read the whole internet before breakfast. They need focused models trained on cleaner, more relevant data. A smaller model with the right knowledge can be more useful than a huge model guessing beautifully.
And this is where OpenLedger’s attribution idea becomes important too. If smaller models are built from specific Datanets, then the value chain becomes easier to understand. Which data helped? Which contributor mattered? Which model improved the output? Who should get credit if the model becomes useful? That is much cleaner than throwing everything into one giant black box and calling it intelligence.
I also like this theme because it feels less like hype and more like infrastructure. Giant models are impressive, but they are expensive, heavy, and not always practical. Specialized models feel more like tools. One model for one job. Another model for another job. Many focused brains instead of one oversized brain pretending to be perfect.
Of course, this is not automatically easy. Small models still need good data. Datanets need quality control. Builders need real reasons to use Model Factory. OpenLoRA needs actual adoption. Otherwise, the whole thing stays as a nice idea on paper, and crypto already has enough nice ideas living permanently on paper.
But the direction makes sense to me. AI does not have to be only a race for the biggest model. It can also be a race for the most useful model. The cleanest data. The best attribution. The easiest deployment. The strongest niche performance.
That is why I think OpenLedger’s model story is underrated. People may focus on agents first because agents are more visible. But agents need models. Models need data. Data needs attribution. And if OpenLedger can make that loop work, then the real win may come from many small, useful models growing inside the ecosystem.
Not model kings.
Model farmers.
Less dramatic maybe… but probably more useful.
@OpenLedger #OpenLedger $OPEN
$LAB
463
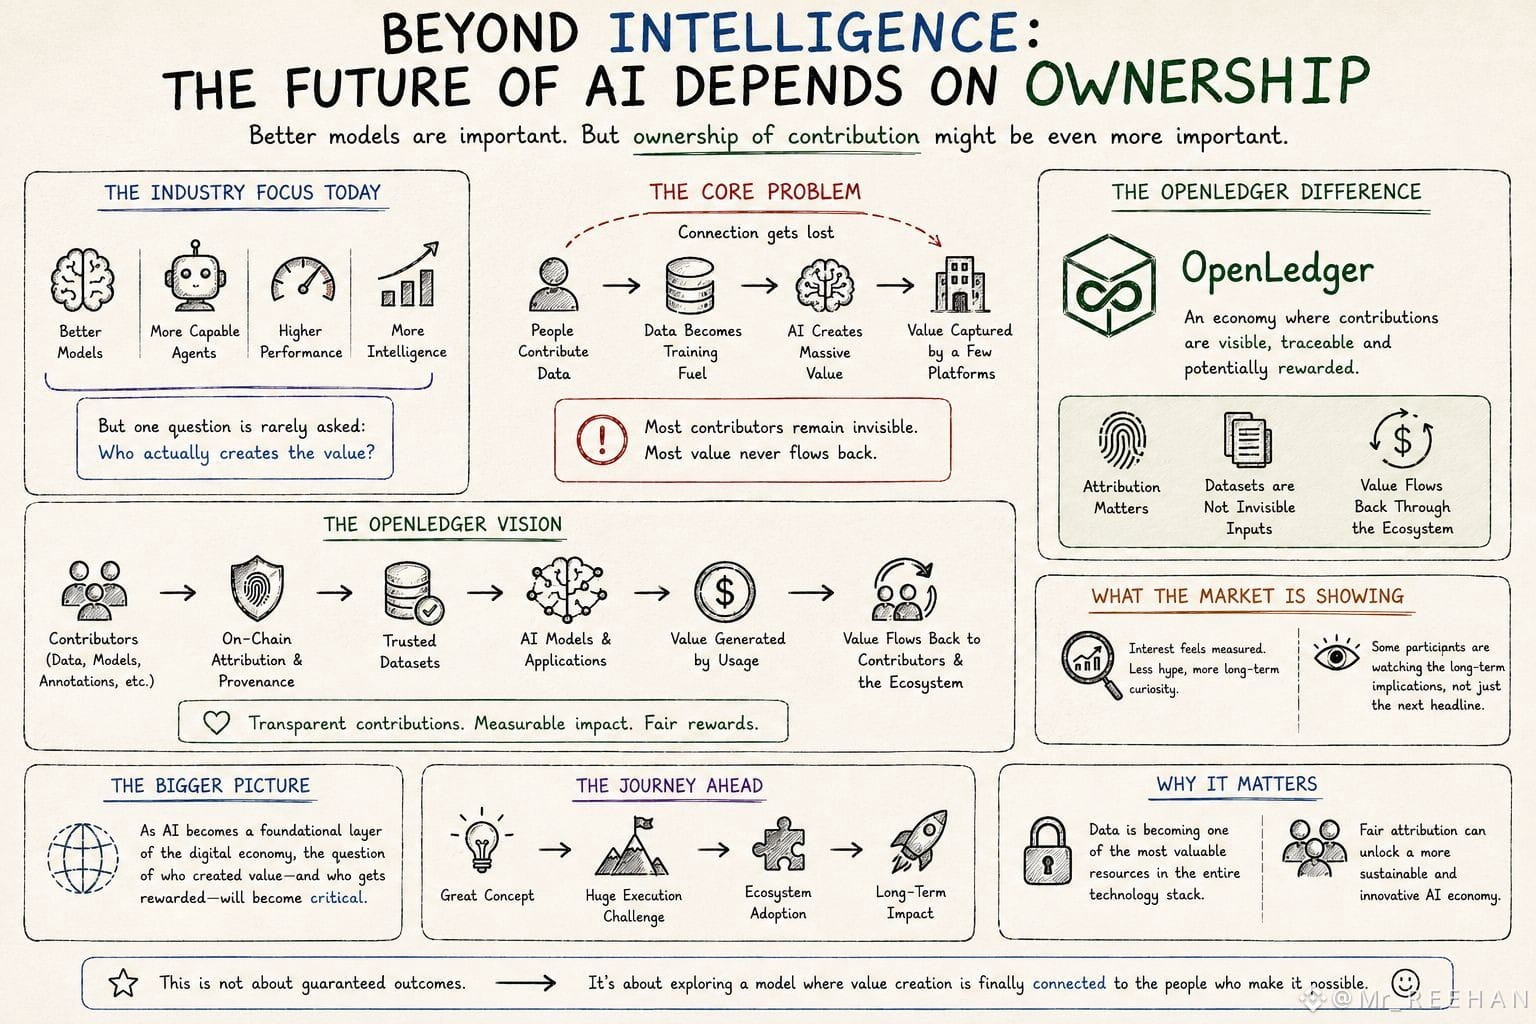
OPENLEDGER ($OPEN) feels like one of those ideas that shows up when the whole market is half tired but still pretending to be early
AI data… models… agents… all turned into something you can rent, trade, monetize. it sounds powerful, almost obvious, like yeah of course knowledge will become liquid someday… but then I sit there staring at it and think, why does everything in crypto always feel like it’s one step away from being real, and also one step away from just another story we keep repeating
I’ve seen this pattern before. new narrative, big words, charts start moving a bit, people start imagining a whole new internet being built overnight… and maybe something does get built, slowly, painfully, but most of it just fades into forgotten Discord servers and half-updated docs
OpenLedger sits right in that uncomfortable zone for me. not a scam vibe, not a guaranteed winner either. just… uncertain energy. like holding a phone with 3 percent battery and deciding whether to keep scrolling or accept reality and put it on charge
and I keep asking myself, who actually pays for rented AI knowledge in a way that sticks, not just experiments or incentives? if that answer becomes real, then yeah… this thing changes. if not, it’s just another beautiful idea floating in crypto space, waiting for gravity
for now I’m just watching it breathe, not touching, not ignoring either
@Openledger #OpenLedger $OPEN
{spot}(OPENUSDT)
OPENLEDGER ($OPEN ) feels like one of those ideas that shows up when the whole market is half tired but still pretending to be early
AI data… models… agents… all turned into something you can rent, trade, monetize. it sounds powerful, almost obvious, like yeah of course knowledge will become liquid someday… but then I sit there staring at it and think, why does everything in crypto always feel like it’s one step away from being real, and also one step away from just another story we keep repeating
I’ve seen this pattern before. new narrative, big words, charts start moving a bit, people start imagining a whole new internet being built overnight… and maybe something does get built, slowly, painfully, but most of it just fades into forgotten Discord servers and half-updated docs
OpenLedger sits right in that uncomfortable zone for me. not a scam vibe, not a guaranteed winner either. just… uncertain energy. like holding a phone with 3 percent battery and deciding whether to keep scrolling or accept reality and put it on charge
and I keep asking myself, who actually pays for rented AI knowledge in a way that sticks, not just experiments or incentives? if that answer becomes real, then yeah… this thing changes. if not, it’s just another beautiful idea floating in crypto space, waiting for gravity
for now I’m just watching it breathe, not touching, not ignoring either
@OpenLedger #OpenLedger $OPEN
AI data… models… agents… all turned into something you can rent, trade, monetize. it sounds powerful, almost obvious, like yeah of course knowledge will become liquid someday… but then I sit there staring at it and think, why does everything in crypto always feel like it’s one step away from being real, and also one step away from just another story we keep repeating
I’ve seen this pattern before. new narrative, big words, charts start moving a bit, people start imagining a whole new internet being built overnight… and maybe something does get built, slowly, painfully, but most of it just fades into forgotten Discord servers and half-updated docs
OpenLedger sits right in that uncomfortable zone for me. not a scam vibe, not a guaranteed winner either. just… uncertain energy. like holding a phone with 3 percent battery and deciding whether to keep scrolling or accept reality and put it on charge
and I keep asking myself, who actually pays for rented AI knowledge in a way that sticks, not just experiments or incentives? if that answer becomes real, then yeah… this thing changes. if not, it’s just another beautiful idea floating in crypto space, waiting for gravity
for now I’m just watching it breathe, not touching, not ignoring either
@OpenLedger #OpenLedger $OPEN
2
2
164
·
--
#openledger $OPEN decentralized physical infrastructure networks are transforming the ai landscape and @Openledger is at the forefront of this shift
Secure data layer protocols are essential for training ai models properly
Watching the open token carefully as the mainnet expands #OpenLedger #Binance #crypto $OPEN
{spot}(OPENUSDT)
$BNB
{spot}(BNBUSDT)
#openledger $OPEN decentralized physical infrastructure networks are transforming the ai landscape and @OpenLedger is at the forefront of this shift
Secure data layer protocols are essential for training ai models properly
Watching the open token carefully as the mainnet expands #OpenLedger #Binance #crypto $OPEN
$BNB
Secure data layer protocols are essential for training ai models properly
Watching the open token carefully as the mainnet expands #OpenLedger #Binance #crypto $OPEN
$BNB
60
·
--
While working through CreatorPad, one thing became impossible to ignore: attribution becomes much harder the moment complexity increases.
OpenLedger aims to make every contribution measurable, yet the challenge isn't tracking influence—it's deciding how much influence truly matters. The deeper the chain of inputs, the easier it becomes for meaningful contributors to disappear behind simplified scoring models.
The real test for AI attribution isn't transparency. It's whether long-tail contributors can retain their share of value as networks scale.
@Openledger | #OpenLedger
$OPEN
{future}(OPENUSDT)
While working through CreatorPad, one thing became impossible to ignore: attribution becomes much harder the moment complexity increases.
OpenLedger aims to make every contribution measurable, yet the challenge isn't tracking influence—it's deciding how much influence truly matters. The deeper the chain of inputs, the easier it becomes for meaningful contributors to disappear behind simplified scoring models.
The real test for AI attribution isn't transparency. It's whether long-tail contributors can retain their share of value as networks scale.
@OpenLedger | #OpenLedger
$OPEN
OpenLedger aims to make every contribution measurable, yet the challenge isn't tracking influence—it's deciding how much influence truly matters. The deeper the chain of inputs, the easier it becomes for meaningful contributors to disappear behind simplified scoring models.
The real test for AI attribution isn't transparency. It's whether long-tail contributors can retain their share of value as networks scale.
@OpenLedger | #OpenLedger
$OPEN
2
2
70
·
--
#openledger $OPEN Honestly, I've become numb to the term "open source." What really makes me pause for @Openledger isn’t that they claim to be open source, but whether vibecoding can sprout those little tools that allow you to pick up where you left off instead of tossing your work aside. Because with execution stacks, it’s not a super feature that stitches everything together, but a bunch of unassuming yet lifesaving components: action previews, missing item alerts, format corrections, step visualizations, and comparison diffs... these are the foundations that truly enable research→action→execute.
My own experience is pretty real: the moment OctoClaw spits out an action, the most likely points of failure aren’t the strategy logic, but rather not catching a dependency in an action step, a parameter being swallowed by default values, or a condition being too vague. If you rely on the human eye, you’ll miss something eventually; one slip-up is enough to give you a headache for a week. So I care more about whether vibecoding can transform these "risk points" into tools, rather than having to rely on my brain to clear them every time. Today you add an action pre-checker, tomorrow you add an action diff to see what step changed between the two sets of actions; the day after, you add an input form to lock down the required fields and formats—this is what makes the execution stack stronger.
Today, I’ll only leave one acceptance criterion (which also best distinguishes "noise" from "ecosystem"): Are there any general components that are repeatedly used by many people and continuously improved upon? It’s not just about my own satisfaction in writing, but whether others are willing to fork it, propose changes, and incorporate it back into their workflow. As long as this reuse chain gets going, @Openledger becomes more than just a product update; it’s growing into a truly sustainable execution toolbox.
@Openledger $OPEN #OpenLedger
#openledger $OPEN Honestly, I've become numb to the term "open source." What really makes me pause for @OpenLedger isn’t that they claim to be open source, but whether vibecoding can sprout those little tools that allow you to pick up where you left off instead of tossing your work aside. Because with execution stacks, it’s not a super feature that stitches everything together, but a bunch of unassuming yet lifesaving components: action previews, missing item alerts, format corrections, step visualizations, and comparison diffs... these are the foundations that truly enable research→action→execute.
My own experience is pretty real: the moment OctoClaw spits out an action, the most likely points of failure aren’t the strategy logic, but rather not catching a dependency in an action step, a parameter being swallowed by default values, or a condition being too vague. If you rely on the human eye, you’ll miss something eventually; one slip-up is enough to give you a headache for a week. So I care more about whether vibecoding can transform these "risk points" into tools, rather than having to rely on my brain to clear them every time. Today you add an action pre-checker, tomorrow you add an action diff to see what step changed between the two sets of actions; the day after, you add an input form to lock down the required fields and formats—this is what makes the execution stack stronger.
Today, I’ll only leave one acceptance criterion (which also best distinguishes "noise" from "ecosystem"): Are there any general components that are repeatedly used by many people and continuously improved upon? It’s not just about my own satisfaction in writing, but whether others are willing to fork it, propose changes, and incorporate it back into their workflow. As long as this reuse chain gets going, @OpenLedger becomes more than just a product update; it’s growing into a truly sustainable execution toolbox.
@OpenLedger $OPEN #OpenLedger
My own experience is pretty real: the moment OctoClaw spits out an action, the most likely points of failure aren’t the strategy logic, but rather not catching a dependency in an action step, a parameter being swallowed by default values, or a condition being too vague. If you rely on the human eye, you’ll miss something eventually; one slip-up is enough to give you a headache for a week. So I care more about whether vibecoding can transform these "risk points" into tools, rather than having to rely on my brain to clear them every time. Today you add an action pre-checker, tomorrow you add an action diff to see what step changed between the two sets of actions; the day after, you add an input form to lock down the required fields and formats—this is what makes the execution stack stronger.
Today, I’ll only leave one acceptance criterion (which also best distinguishes "noise" from "ecosystem"): Are there any general components that are repeatedly used by many people and continuously improved upon? It’s not just about my own satisfaction in writing, but whether others are willing to fork it, propose changes, and incorporate it back into their workflow. As long as this reuse chain gets going, @OpenLedger becomes more than just a product update; it’s growing into a truly sustainable execution toolbox.
@OpenLedger $OPEN #OpenLedger
75

·
--
Verified
Article
OpenLedger Feels Like a Contributor Play… But $OPEN May Be Pricing the Long Tail of Human InputTo be honest, there's a quiet frustration I've carried since 2022 from contributing to online spaces.
Not anger.
Just a low-level awareness that never fully goes away.
I've written detailed market analyses on public forums. Shared research breakdowns that get hundreds of shares. Spent real hours putting together threads that other people build on, remix, quote in their own work. Some of those posts still get referenced today in conversations I'm not even part of.
I got paid exactly once for each of them. Usually nothing at all.
The value kept moving forward. My economic connection to it stopped the moment I hit publish.
That specific experience is what makes me read OpenLedger's attribution model differently than I read most things in this space right now.
Because what it actually describes isn't just a better version of one-time contributor payments. It describes a structurally different relationship between contribution and economic outcome across time.
Here's the part that holds my attention.
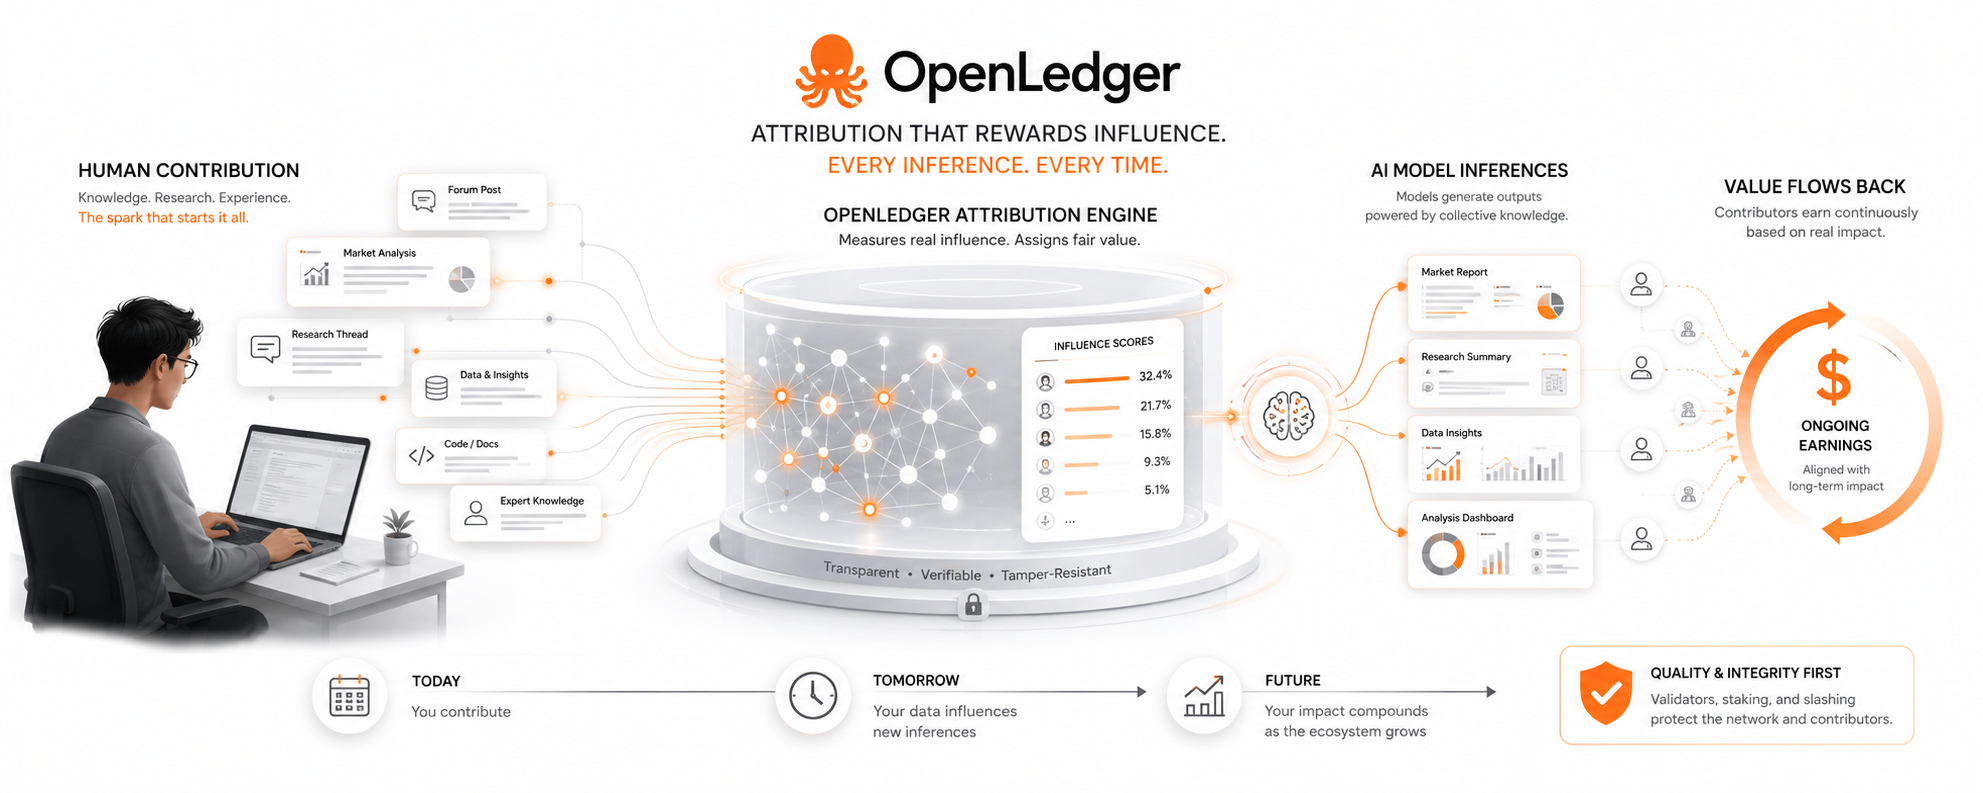
When a specialized model on OpenLedger handles a request, the system calculates how much each individual data contribution actually shaped that specific output. Not equally across all contributors. Each data point carries an influence score based on its measured impact on the result. The contributor whose data scores higher on that particular output earns a proportionally larger cut of the contributor fee pool from that inference.
Every inference. Not just the first time the model runs.
So a data submission doesn't carry a fixed lifetime value locked in at the moment of contribution. Its economic value keeps recalculating with every model call it influences. A carefully constructed contribution to an actively used model keeps generating income the way a well-cited reference document keeps getting pulled into new research. Not because someone is being generous. Because the measurement system ties earning directly to ongoing measured impact.
That structural gap matters more than it appears at first glance.
In a standard data marketplace, quality beyond a basic acceptable threshold doesn't change your outcome. Fast submission at minimum quality and slow submission with deep domain expertise produce the same result once payment clears. The incentive structure doesn't distinguish between them after the transaction closes.
In a system where ongoing influence determines ongoing earnings, precision becomes a long-term financial decision rather than a professional courtesy. A contributor who understands their domain deeply and submits data that keeps scoring strongly on future inferences isn't just being thorough. They're compounding a position in a model's future output. $US
That changes who the network rationally attracts over time.
But I want to sit with the uncomfortable side honestly.
Ongoing attribution is a significantly harder technical problem than initial attribution.
Proving that a data point contributed at the moment of submission is relatively clean. A timestamp exists. A record exists. The data either shaped early training or it didn't.
Proving that the same contribution continues carrying genuine influence months later, across an expanding contributor pool, as the model receives further updates and fine-tuning, is an entirely different challenge. Individual influence scores compress naturally as contributor pools grow. What carries strong weight in an early training phase faces increasing competition from newer, more recent submissions over time. A contributor who builds a strong position in a model's early stages doesn't automatically maintain that position indefinitely. The math dilutes as the total pool expands around it.
And gaming pressure compounds in proportion to how financially meaningful the earning streams become.
When ongoing income depends on algorithmic scores, optimizing toward the score rather than toward genuine model improvement becomes rational for sophisticated actors.
The gap between what the metric measures and what it was designed to reward widens under exactly the conditions where the financial incentive to exploit it grows strongest.
OpenLedger's validator mechanics and staking penalties exist specifically to push against this. Economic costs attach to low-quality submissions.
But whether those resistance mechanisms hold their integrity as network value scales and the reward for gaming rises alongside it is a genuinely open question.
OPEN prices whether that question finds a durable answer.
Not just whether the infrastructure for measuring contribution gets built. Whether it stays accurate enough under real financial pressure to justify the long-term quality decisions contributors make based on trusting it.
That's a considerably harder thing to price than infrastructure adoption alone.
And here's what keeps circling back in my thinking after all of this. $LAB
If knowledge contributed to AI systems carried an ongoing economic relationship rather than a closed one-time transaction... would the people currently giving that knowledge away for nothing start making different decisions about where and how precisely they contribute?
And if they do... what does the quality of AI development actually look like on the other side of that behavioral shift?
#OpenLedger @Openledger $OPEN
OpenLedger Feels Like a Contributor Play… But $OPEN May Be Pricing the Long Tail of Human Input
To be honest, there's a quiet frustration I've carried since 2022 from contributing to online spaces.
Not anger.
Just a low-level awareness that never fully goes away.
I've written detailed market analyses on public forums. Shared research breakdowns that get hundreds of shares. Spent real hours putting together threads that other people build on, remix, quote in their own work. Some of those posts still get referenced today in conversations I'm not even part of.
I got paid exactly once for each of them. Usually nothing at all.
The value kept moving forward. My economic connection to it stopped the moment I hit publish.
That specific experience is what makes me read OpenLedger's attribution model differently than I read most things in this space right now.
Because what it actually describes isn't just a better version of one-time contributor payments. It describes a structurally different relationship between contribution and economic outcome across time.
Here's the part that holds my attention.
When a specialized model on OpenLedger handles a request, the system calculates how much each individual data contribution actually shaped that specific output. Not equally across all contributors. Each data point carries an influence score based on its measured impact on the result. The contributor whose data scores higher on that particular output earns a proportionally larger cut of the contributor fee pool from that inference.
Every inference. Not just the first time the model runs.
So a data submission doesn't carry a fixed lifetime value locked in at the moment of contribution. Its economic value keeps recalculating with every model call it influences. A carefully constructed contribution to an actively used model keeps generating income the way a well-cited reference document keeps getting pulled into new research. Not because someone is being generous. Because the measurement system ties earning directly to ongoing measured impact.
That structural gap matters more than it appears at first glance.
In a standard data marketplace, quality beyond a basic acceptable threshold doesn't change your outcome. Fast submission at minimum quality and slow submission with deep domain expertise produce the same result once payment clears. The incentive structure doesn't distinguish between them after the transaction closes.
In a system where ongoing influence determines ongoing earnings, precision becomes a long-term financial decision rather than a professional courtesy. A contributor who understands their domain deeply and submits data that keeps scoring strongly on future inferences isn't just being thorough. They're compounding a position in a model's future output. $US
That changes who the network rationally attracts over time.
But I want to sit with the uncomfortable side honestly.
Ongoing attribution is a significantly harder technical problem than initial attribution.
Proving that a data point contributed at the moment of submission is relatively clean. A timestamp exists. A record exists. The data either shaped early training or it didn't.
Proving that the same contribution continues carrying genuine influence months later, across an expanding contributor pool, as the model receives further updates and fine-tuning, is an entirely different challenge. Individual influence scores compress naturally as contributor pools grow. What carries strong weight in an early training phase faces increasing competition from newer, more recent submissions over time. A contributor who builds a strong position in a model's early stages doesn't automatically maintain that position indefinitely. The math dilutes as the total pool expands around it.
And gaming pressure compounds in proportion to how financially meaningful the earning streams become.
When ongoing income depends on algorithmic scores, optimizing toward the score rather than toward genuine model improvement becomes rational for sophisticated actors.
The gap between what the metric measures and what it was designed to reward widens under exactly the conditions where the financial incentive to exploit it grows strongest.
OpenLedger's validator mechanics and staking penalties exist specifically to push against this. Economic costs attach to low-quality submissions.
But whether those resistance mechanisms hold their integrity as network value scales and the reward for gaming rises alongside it is a genuinely open question.
OPEN prices whether that question finds a durable answer.
Not just whether the infrastructure for measuring contribution gets built. Whether it stays accurate enough under real financial pressure to justify the long-term quality decisions contributors make based on trusting it.
That's a considerably harder thing to price than infrastructure adoption alone.
And here's what keeps circling back in my thinking after all of this. $LAB
If knowledge contributed to AI systems carried an ongoing economic relationship rather than a closed one-time transaction... would the people currently giving that knowledge away for nothing start making different decisions about where and how precisely they contribute?
And if they do... what does the quality of AI development actually look like on the other side of that behavioral shift?
#OpenLedger @OpenLedger $OPEN
Not anger.
Just a low-level awareness that never fully goes away.
I've written detailed market analyses on public forums. Shared research breakdowns that get hundreds of shares. Spent real hours putting together threads that other people build on, remix, quote in their own work. Some of those posts still get referenced today in conversations I'm not even part of.
I got paid exactly once for each of them. Usually nothing at all.
The value kept moving forward. My economic connection to it stopped the moment I hit publish.
That specific experience is what makes me read OpenLedger's attribution model differently than I read most things in this space right now.
Because what it actually describes isn't just a better version of one-time contributor payments. It describes a structurally different relationship between contribution and economic outcome across time.
Here's the part that holds my attention.
When a specialized model on OpenLedger handles a request, the system calculates how much each individual data contribution actually shaped that specific output. Not equally across all contributors. Each data point carries an influence score based on its measured impact on the result. The contributor whose data scores higher on that particular output earns a proportionally larger cut of the contributor fee pool from that inference.
Every inference. Not just the first time the model runs.
So a data submission doesn't carry a fixed lifetime value locked in at the moment of contribution. Its economic value keeps recalculating with every model call it influences. A carefully constructed contribution to an actively used model keeps generating income the way a well-cited reference document keeps getting pulled into new research. Not because someone is being generous. Because the measurement system ties earning directly to ongoing measured impact.
That structural gap matters more than it appears at first glance.
In a standard data marketplace, quality beyond a basic acceptable threshold doesn't change your outcome. Fast submission at minimum quality and slow submission with deep domain expertise produce the same result once payment clears. The incentive structure doesn't distinguish between them after the transaction closes.
In a system where ongoing influence determines ongoing earnings, precision becomes a long-term financial decision rather than a professional courtesy. A contributor who understands their domain deeply and submits data that keeps scoring strongly on future inferences isn't just being thorough. They're compounding a position in a model's future output. $US
That changes who the network rationally attracts over time.
But I want to sit with the uncomfortable side honestly.
Ongoing attribution is a significantly harder technical problem than initial attribution.
Proving that a data point contributed at the moment of submission is relatively clean. A timestamp exists. A record exists. The data either shaped early training or it didn't.
Proving that the same contribution continues carrying genuine influence months later, across an expanding contributor pool, as the model receives further updates and fine-tuning, is an entirely different challenge. Individual influence scores compress naturally as contributor pools grow. What carries strong weight in an early training phase faces increasing competition from newer, more recent submissions over time. A contributor who builds a strong position in a model's early stages doesn't automatically maintain that position indefinitely. The math dilutes as the total pool expands around it.
And gaming pressure compounds in proportion to how financially meaningful the earning streams become.
When ongoing income depends on algorithmic scores, optimizing toward the score rather than toward genuine model improvement becomes rational for sophisticated actors.
The gap between what the metric measures and what it was designed to reward widens under exactly the conditions where the financial incentive to exploit it grows strongest.
OpenLedger's validator mechanics and staking penalties exist specifically to push against this. Economic costs attach to low-quality submissions.
But whether those resistance mechanisms hold their integrity as network value scales and the reward for gaming rises alongside it is a genuinely open question.
OPEN prices whether that question finds a durable answer.
Not just whether the infrastructure for measuring contribution gets built. Whether it stays accurate enough under real financial pressure to justify the long-term quality decisions contributors make based on trusting it.
That's a considerably harder thing to price than infrastructure adoption alone.
And here's what keeps circling back in my thinking after all of this. $LAB
If knowledge contributed to AI systems carried an ongoing economic relationship rather than a closed one-time transaction... would the people currently giving that knowledge away for nothing start making different decisions about where and how precisely they contribute?
And if they do... what does the quality of AI development actually look like on the other side of that behavioral shift?
#OpenLedger @OpenLedger $OPEN
763
·
--
Article
I crunched the numbers: How much can you make in a month on OpenLedger?Last month, I was just chilling with nothing to do, so I decided to seriously dive into the OpenLedger data contribution task. Not just tossing up a couple of files here and there, but dedicating two hours every day to sourcing high-quality data, doing cleaning and labeling. I kept this up for a full thirty days. I wanted to see how this 'profit-sharing based on contributions' slogan actually translates into earnings for a regular Joe.
First off, here's the bottom line: I've contributed over four hundred valid data entries, and my attribution score is averaging above mid-tier. The $OPEN I've pocketed is worth around $160 based on the market rate at that time. Sounds decent, right? But when you break it down, considering my hourly wage, it's two hours a day for thirty days, totaling sixty hours. So $160 divided by sixty comes out to less than three bucks an hour. If I took a gig handing out flyers, I'd be raking in ten bucks an hour!
I crunched the numbers: How much can you make in a month on OpenLedger?
Last month, I was just chilling with nothing to do, so I decided to seriously dive into the OpenLedger data contribution task. Not just tossing up a couple of files here and there, but dedicating two hours every day to sourcing high-quality data, doing cleaning and labeling. I kept this up for a full thirty days. I wanted to see how this 'profit-sharing based on contributions' slogan actually translates into earnings for a regular Joe.
First off, here's the bottom line: I've contributed over four hundred valid data entries, and my attribution score is averaging above mid-tier. The $OPEN I've pocketed is worth around $160 based on the market rate at that time. Sounds decent, right? But when you break it down, considering my hourly wage, it's two hours a day for thirty days, totaling sixty hours. So $160 divided by sixty comes out to less than three bucks an hour. If I took a gig handing out flyers, I'd be raking in ten bucks an hour!
First off, here's the bottom line: I've contributed over four hundred valid data entries, and my attribution score is averaging above mid-tier. The $OPEN I've pocketed is worth around $160 based on the market rate at that time. Sounds decent, right? But when you break it down, considering my hourly wage, it's two hours a day for thirty days, totaling sixty hours. So $160 divided by sixty comes out to less than three bucks an hour. If I took a gig handing out flyers, I'd be raking in ten bucks an hour!
473
·
--

Article
The Future of AI Monetization Starts With OpenLedgerArtificial Intelligence is rapidly becoming one of the most valuable technologies of our time. Every day, new AI models, datasets, and autonomous agents are being created, generating immense value across industries. However, one challenge remains unresolved: how can contributors fairly monetize the data, models, and intelligence they create?
This is where @Openledger introduces a compelling vision. OpenLedger is an AI-focused blockchain designed to unlock liquidity for data, models, and agents, creating an ecosystem where AI assets can become productive, tradable, and economically valuable.
Traditional AI development often concentrates value in the hands of a few large organizations. Data providers, independent developers, and smaller communities may contribute significantly to innovation but receive only a fraction of the rewards. OpenLedger aims to change this dynamic by building infrastructure that enables transparent ownership, attribution, and monetization.
The concept is powerful. Data can be treated as an asset. AI models can be recognized as economic resources. Autonomous agents can participate in decentralized networks while generating measurable value. Through blockchain technology, these assets gain liquidity and can be integrated into a broader digital economy.
One of the most exciting aspects of OpenLedger is its focus on creating a marketplace for intelligence itself. As AI adoption continues to accelerate, demand for high-quality datasets, specialized models, and intelligent agents will grow. OpenLedger provides a foundation where these resources can be exchanged, rewarded, and scaled in a transparent environment.
The combination of blockchain and AI represents a major technological shift. Blockchain provides trust, ownership, and transparent value distribution, while AI provides automation, reasoning, and productivity. OpenLedger stands at the intersection of these two transformative technologies, helping bridge the gap between innovation and economic participation.
For developers, OpenLedger offers new monetization opportunities. For data contributors, it creates pathways to receive value for their work. For users and businesses, it enables access to a growing ecosystem of AI-powered resources. This alignment of incentives could play a significant role in accelerating the development of decentralized AI infrastructure.
As the digital economy evolves, platforms that successfully connect AI innovation with fair value distribution may become critical components of the next generation of the internet. OpenLedger is building toward that future by enabling data, models, and agents to become liquid assets within a decentralized ecosystem.
The vision behind $OPEN is not simply about creating another blockchain. It is about establishing the economic rails for an AI-driven world where contributors are rewarded, innovation is encouraged, and intelligence can flow freely across decentralized networks.
#OpenLedger $OPEN @Openledger
The Future of AI Monetization Starts With OpenLedger
Artificial Intelligence is rapidly becoming one of the most valuable technologies of our time. Every day, new AI models, datasets, and autonomous agents are being created, generating immense value across industries. However, one challenge remains unresolved: how can contributors fairly monetize the data, models, and intelligence they create?
This is where @OpenLedger introduces a compelling vision. OpenLedger is an AI-focused blockchain designed to unlock liquidity for data, models, and agents, creating an ecosystem where AI assets can become productive, tradable, and economically valuable.
Traditional AI development often concentrates value in the hands of a few large organizations. Data providers, independent developers, and smaller communities may contribute significantly to innovation but receive only a fraction of the rewards. OpenLedger aims to change this dynamic by building infrastructure that enables transparent ownership, attribution, and monetization.
The concept is powerful. Data can be treated as an asset. AI models can be recognized as economic resources. Autonomous agents can participate in decentralized networks while generating measurable value. Through blockchain technology, these assets gain liquidity and can be integrated into a broader digital economy.
One of the most exciting aspects of OpenLedger is its focus on creating a marketplace for intelligence itself. As AI adoption continues to accelerate, demand for high-quality datasets, specialized models, and intelligent agents will grow. OpenLedger provides a foundation where these resources can be exchanged, rewarded, and scaled in a transparent environment.
The combination of blockchain and AI represents a major technological shift. Blockchain provides trust, ownership, and transparent value distribution, while AI provides automation, reasoning, and productivity. OpenLedger stands at the intersection of these two transformative technologies, helping bridge the gap between innovation and economic participation.
For developers, OpenLedger offers new monetization opportunities. For data contributors, it creates pathways to receive value for their work. For users and businesses, it enables access to a growing ecosystem of AI-powered resources. This alignment of incentives could play a significant role in accelerating the development of decentralized AI infrastructure.
As the digital economy evolves, platforms that successfully connect AI innovation with fair value distribution may become critical components of the next generation of the internet. OpenLedger is building toward that future by enabling data, models, and agents to become liquid assets within a decentralized ecosystem.
The vision behind $OPEN is not simply about creating another blockchain. It is about establishing the economic rails for an AI-driven world where contributors are rewarded, innovation is encouraged, and intelligence can flow freely across decentralized networks.
#OpenLedger $OPEN @Openledger
This is where @OpenLedger introduces a compelling vision. OpenLedger is an AI-focused blockchain designed to unlock liquidity for data, models, and agents, creating an ecosystem where AI assets can become productive, tradable, and economically valuable.
Traditional AI development often concentrates value in the hands of a few large organizations. Data providers, independent developers, and smaller communities may contribute significantly to innovation but receive only a fraction of the rewards. OpenLedger aims to change this dynamic by building infrastructure that enables transparent ownership, attribution, and monetization.
The concept is powerful. Data can be treated as an asset. AI models can be recognized as economic resources. Autonomous agents can participate in decentralized networks while generating measurable value. Through blockchain technology, these assets gain liquidity and can be integrated into a broader digital economy.
One of the most exciting aspects of OpenLedger is its focus on creating a marketplace for intelligence itself. As AI adoption continues to accelerate, demand for high-quality datasets, specialized models, and intelligent agents will grow. OpenLedger provides a foundation where these resources can be exchanged, rewarded, and scaled in a transparent environment.
The combination of blockchain and AI represents a major technological shift. Blockchain provides trust, ownership, and transparent value distribution, while AI provides automation, reasoning, and productivity. OpenLedger stands at the intersection of these two transformative technologies, helping bridge the gap between innovation and economic participation.
For developers, OpenLedger offers new monetization opportunities. For data contributors, it creates pathways to receive value for their work. For users and businesses, it enables access to a growing ecosystem of AI-powered resources. This alignment of incentives could play a significant role in accelerating the development of decentralized AI infrastructure.
As the digital economy evolves, platforms that successfully connect AI innovation with fair value distribution may become critical components of the next generation of the internet. OpenLedger is building toward that future by enabling data, models, and agents to become liquid assets within a decentralized ecosystem.
The vision behind $OPEN is not simply about creating another blockchain. It is about establishing the economic rails for an AI-driven world where contributors are rewarded, innovation is encouraged, and intelligence can flow freely across decentralized networks.
#OpenLedger $OPEN @Openledger
42
Article
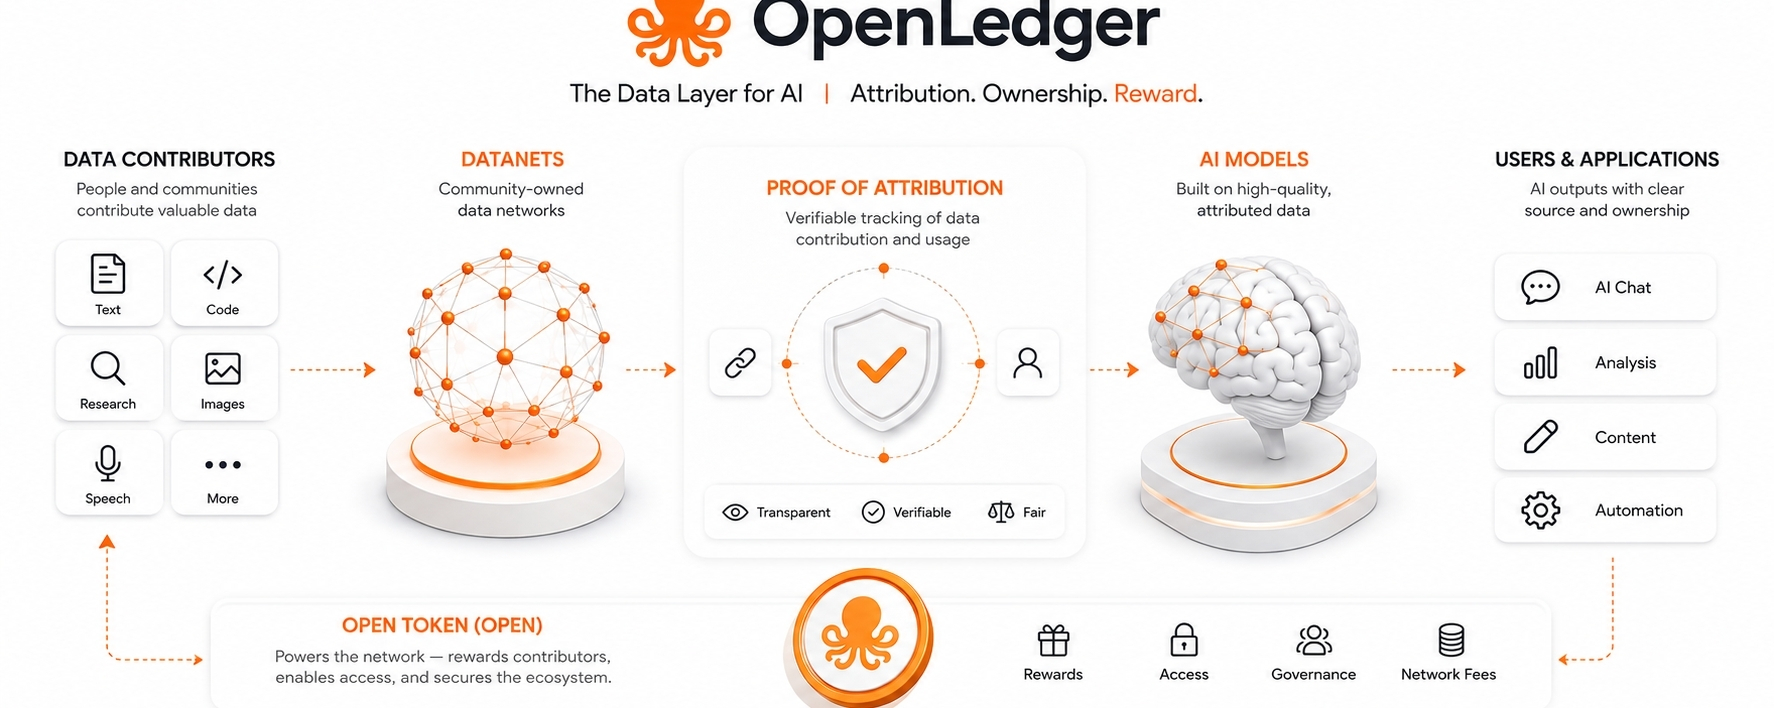
OpenLedger and the Uncomfortable Question of Who Really Owns AI DataOpenLedger makes me think about one of the ugliest things in crypto and AI at the same time: everybody wants the reward, but almost nobody wants to talk about the mess underneath. The data. The source. The people who actually contributed something. The fake users. The farmers. The invisible work that gets swallowed by a system and then sold back to everyone with a cleaner logo.
Look, I am tired of AI crypto pitches.
Really tired.
Every week there is another project acting like it found the final answer. Another token. Another dashboard. Another thread explaining why this is the “future of intelligence” or whatever phrase is working this month.
At some point, you stop clapping.
You just ask: what is actually broken here?
With OpenLedger, at least the broken part is real.
AI models need data. Not magic. Not vibes. Data. Human work. Community knowledge. Niche research. Code. Writing. Trading behavior. Local knowledge. Weird little corners of the internet that only matter because real people spent time creating them.
Then the model eats all of it.
And the contributor disappears.
That part bothers me.
It should bother more people.
OpenLedger is trying to deal with that layer. Not the shiny output layer where everyone types a prompt and pretends the machine is smart by itself. I mean the under-the-hood part. The boring plumbing. The part where data comes from somewhere, someone contributed it, and maybe that contribution should not vanish forever.
It is not flashy.
It is just necessary.
Honestly, that is why I find it more interesting than most AI coins. Not because it sounds perfect. It does not. Not because I think crypto magically fixes AI. It does not. But because OpenLedger is focused on a real pain point: attribution.
Who gave the data?
Who helped train the model?
Who deserves credit?
Who gets paid?
Who gets erased?
These questions are not clean. They are uncomfortable. And that is probably why most projects avoid them.
The thing is, crypto people have already lived through the ugly side of incentive systems. We know what happens when rewards are involved. We have seen airdrops get farmed into the ground. We have seen fake users flood testnets. We have seen communities act loyal until the claim page opens. We have seen “organic traction” turn out to be wallets chasing points.
So when OpenLedger talks about rewarding data contributors, my first reaction is not blind praise.
My first reaction is: okay, but how do you stop the garbage?
Because people will try to game it.
They always do.
If there is a reward for contributing data, some users will contribute useful data. Others will dump junk. Duplicate content. Low-effort material. Sybil accounts. Recycled noise. Anything that looks like activity from the outside.
That is the mess OpenLedger has to survive.
And it is a serious mess.
This is where the project becomes interesting, but also hard. Proof of Attribution sounds like the right direction, but AI attribution is not simple. A model does not learn like a person reading one paragraph and saying, “Thanks, this exact idea came from here.” It absorbs patterns. It mixes sources. It compresses information. It becomes very hard to say who contributed what in a way that feels fair.
So OpenLedger is not solving some easy little tracking problem.
It is walking into one of the most annoying parts of AI.
Maybe that is why I respect the attempt.
Not the hype around it. The attempt.
The idea of Datanets also makes sense to me because specialized data is probably where this has a better chance. I do not really believe every crypto AI project needs to fight OpenAI or Google or the giant labs directly. That usually sounds like fantasy. Those companies have money, talent, compute, distribution, and lawyers. Crypto has Telegram groups arguing about unlocks.
But focused data networks?
That feels more realistic.
A niche community building around a specific type of data. A model trained for a specific use case. Contributors getting tracked. Value not just disappearing into some closed machine. That is not some glamorous story, but it is closer to actual infrastructure.
And crypto needs more of that.
Less theatre.
More plumbing.
Still, OpenLedger has a hard road. It has to prove that people will contribute quality data, not just farm rewards. It has to prove that builders care enough to use the system. It has to prove that attribution can be trusted, even if it is not perfect. It has to prove that the token is connected to real usage, not just another reason for people to speculate during an AI cycle.
That last part matters.
Because there is a token, and once there is a token, everything changes.
People stop asking what the system does and start asking when it lists, when it pumps, when the next campaign starts, when the next reward drops. The project becomes a market object before it becomes useful infrastructure. That is the normal crypto disease.
OpenLedger is not immune to it.
No project is.
OPEN having a role in fees, rewards, and network activity gives it some logic. Fine. That is better than a token that only exists for governance theatre. But utility on paper is not enough. If the network does not create real demand, the token becomes another circular machine.
Rewards bring users.
Users create activity.
Activity creates hype.
Hype supports the token.
Then rewards slow down.
And suddenly everyone finds out what was real.
We have seen that movie too many times.
That is why I do not want to over-sell OpenLedger. The idea is strong enough without pretending it is guaranteed. It might take time. It might be messy. It might work only in certain niches first. It might struggle with quality control. It might attract more farmers than builders early on.
That would not surprise me.
Actually, I expect some of that.
But the project is still touching something important. AI has a value extraction problem. A lot of people contribute to the knowledge layer, but only a few platforms capture most of the upside. OpenLedger is trying to make that contribution layer visible and usable.
That is worth watching.
Not worshipping.
Watching.
Look, I do not need OpenLedger to become some giant world-changing thing for it to matter. Crypto people love making everything dramatic. Sometimes a project only needs to fix one ugly piece of infrastructure that everyone else keeps ignoring.
Data attribution is one of those ugly pieces.
Nobody wants to think about it when the model output looks clean. Nobody wants to ask where the value came from when the demo works. Nobody wants to deal with the boring accounting of contribution, ownership, and reward.
But eventually, that stuff matters.
Especially if AI keeps eating more of the internet.
The hard part for OpenLedger is trust. Not just trust in the chain. Trust in the process. Trust that contribution is measured fairly. Trust that the reward system does not become a farming game. Trust that the datasets are actually useful. Trust that builders are not just there for incentives. Trust that the whole thing is not another AI narrative wearing infrastructure clothing.
That is a lot of trust to earn.
And it will not be earned through slogans.
It will be earned through boring usage.
People contributing real data. Builders making models that actually work. Users paying because the output is useful. Communities staying after the hype cools down. Less noise. More proof.
That is the only version of OpenLedger that matters to me.
Maybe it gets there.
Maybe it does not.
The thing is, I would rather watch a project trying to solve a boring, real problem than another shiny AI token pretending a chatbot needs a coin. OpenLedger at least lives closer to the actual mess: data, attribution, incentives, contributors, and model value.
That is not clean.
That is not easy.
But it feels closer to reality.
And after enough crypto cycles, reality starts to matter more than the pitch.
@Openledger
#OpenLedger
$OPEN
OpenLedger and the Uncomfortable Question of Who Really Owns AI Data
OpenLedger makes me think about one of the ugliest things in crypto and AI at the same time: everybody wants the reward, but almost nobody wants to talk about the mess underneath. The data. The source. The people who actually contributed something. The fake users. The farmers. The invisible work that gets swallowed by a system and then sold back to everyone with a cleaner logo.
Look, I am tired of AI crypto pitches.
Really tired.
Every week there is another project acting like it found the final answer. Another token. Another dashboard. Another thread explaining why this is the “future of intelligence” or whatever phrase is working this month.
At some point, you stop clapping.
You just ask: what is actually broken here?
With OpenLedger, at least the broken part is real.
AI models need data. Not magic. Not vibes. Data. Human work. Community knowledge. Niche research. Code. Writing. Trading behavior. Local knowledge. Weird little corners of the internet that only matter because real people spent time creating them.
Then the model eats all of it.
And the contributor disappears.
That part bothers me.
It should bother more people.
OpenLedger is trying to deal with that layer. Not the shiny output layer where everyone types a prompt and pretends the machine is smart by itself. I mean the under-the-hood part. The boring plumbing. The part where data comes from somewhere, someone contributed it, and maybe that contribution should not vanish forever.
It is not flashy.
It is just necessary.
Honestly, that is why I find it more interesting than most AI coins. Not because it sounds perfect. It does not. Not because I think crypto magically fixes AI. It does not. But because OpenLedger is focused on a real pain point: attribution.
Who gave the data?
Who helped train the model?
Who deserves credit?
Who gets paid?
Who gets erased?
These questions are not clean. They are uncomfortable. And that is probably why most projects avoid them.
The thing is, crypto people have already lived through the ugly side of incentive systems. We know what happens when rewards are involved. We have seen airdrops get farmed into the ground. We have seen fake users flood testnets. We have seen communities act loyal until the claim page opens. We have seen “organic traction” turn out to be wallets chasing points.
So when OpenLedger talks about rewarding data contributors, my first reaction is not blind praise.
My first reaction is: okay, but how do you stop the garbage?
Because people will try to game it.
They always do.
If there is a reward for contributing data, some users will contribute useful data. Others will dump junk. Duplicate content. Low-effort material. Sybil accounts. Recycled noise. Anything that looks like activity from the outside.
That is the mess OpenLedger has to survive.
And it is a serious mess.
This is where the project becomes interesting, but also hard. Proof of Attribution sounds like the right direction, but AI attribution is not simple. A model does not learn like a person reading one paragraph and saying, “Thanks, this exact idea came from here.” It absorbs patterns. It mixes sources. It compresses information. It becomes very hard to say who contributed what in a way that feels fair.
So OpenLedger is not solving some easy little tracking problem.
It is walking into one of the most annoying parts of AI.
Maybe that is why I respect the attempt.
Not the hype around it. The attempt.
The idea of Datanets also makes sense to me because specialized data is probably where this has a better chance. I do not really believe every crypto AI project needs to fight OpenAI or Google or the giant labs directly. That usually sounds like fantasy. Those companies have money, talent, compute, distribution, and lawyers. Crypto has Telegram groups arguing about unlocks.
But focused data networks?
That feels more realistic.
A niche community building around a specific type of data. A model trained for a specific use case. Contributors getting tracked. Value not just disappearing into some closed machine. That is not some glamorous story, but it is closer to actual infrastructure.
And crypto needs more of that.
Less theatre.
More plumbing.
Still, OpenLedger has a hard road. It has to prove that people will contribute quality data, not just farm rewards. It has to prove that builders care enough to use the system. It has to prove that attribution can be trusted, even if it is not perfect. It has to prove that the token is connected to real usage, not just another reason for people to speculate during an AI cycle.
That last part matters.
Because there is a token, and once there is a token, everything changes.
People stop asking what the system does and start asking when it lists, when it pumps, when the next campaign starts, when the next reward drops. The project becomes a market object before it becomes useful infrastructure. That is the normal crypto disease.
OpenLedger is not immune to it.
No project is.
OPEN having a role in fees, rewards, and network activity gives it some logic. Fine. That is better than a token that only exists for governance theatre. But utility on paper is not enough. If the network does not create real demand, the token becomes another circular machine.
Rewards bring users.
Users create activity.
Activity creates hype.
Hype supports the token.
Then rewards slow down.
And suddenly everyone finds out what was real.
We have seen that movie too many times.
That is why I do not want to over-sell OpenLedger. The idea is strong enough without pretending it is guaranteed. It might take time. It might be messy. It might work only in certain niches first. It might struggle with quality control. It might attract more farmers than builders early on.
That would not surprise me.
Actually, I expect some of that.
But the project is still touching something important. AI has a value extraction problem. A lot of people contribute to the knowledge layer, but only a few platforms capture most of the upside. OpenLedger is trying to make that contribution layer visible and usable.
That is worth watching.
Not worshipping.
Watching.
Look, I do not need OpenLedger to become some giant world-changing thing for it to matter. Crypto people love making everything dramatic. Sometimes a project only needs to fix one ugly piece of infrastructure that everyone else keeps ignoring.
Data attribution is one of those ugly pieces.
Nobody wants to think about it when the model output looks clean. Nobody wants to ask where the value came from when the demo works. Nobody wants to deal with the boring accounting of contribution, ownership, and reward.
But eventually, that stuff matters.
Especially if AI keeps eating more of the internet.
The hard part for OpenLedger is trust. Not just trust in the chain. Trust in the process. Trust that contribution is measured fairly. Trust that the reward system does not become a farming game. Trust that the datasets are actually useful. Trust that builders are not just there for incentives. Trust that the whole thing is not another AI narrative wearing infrastructure clothing.
That is a lot of trust to earn.
And it will not be earned through slogans.
It will be earned through boring usage.
People contributing real data. Builders making models that actually work. Users paying because the output is useful. Communities staying after the hype cools down. Less noise. More proof.
That is the only version of OpenLedger that matters to me.
Maybe it gets there.
Maybe it does not.
The thing is, I would rather watch a project trying to solve a boring, real problem than another shiny AI token pretending a chatbot needs a coin. OpenLedger at least lives closer to the actual mess: data, attribution, incentives, contributors, and model value.
That is not clean.
That is not easy.
But it feels closer to reality.
And after enough crypto cycles, reality starts to matter more than the pitch.
@OpenLedger
#OpenLedger
$OPEN
Look, I am tired of AI crypto pitches.
Really tired.
Every week there is another project acting like it found the final answer. Another token. Another dashboard. Another thread explaining why this is the “future of intelligence” or whatever phrase is working this month.
At some point, you stop clapping.
You just ask: what is actually broken here?
With OpenLedger, at least the broken part is real.
AI models need data. Not magic. Not vibes. Data. Human work. Community knowledge. Niche research. Code. Writing. Trading behavior. Local knowledge. Weird little corners of the internet that only matter because real people spent time creating them.
Then the model eats all of it.
And the contributor disappears.
That part bothers me.
It should bother more people.
OpenLedger is trying to deal with that layer. Not the shiny output layer where everyone types a prompt and pretends the machine is smart by itself. I mean the under-the-hood part. The boring plumbing. The part where data comes from somewhere, someone contributed it, and maybe that contribution should not vanish forever.
It is not flashy.
It is just necessary.
Honestly, that is why I find it more interesting than most AI coins. Not because it sounds perfect. It does not. Not because I think crypto magically fixes AI. It does not. But because OpenLedger is focused on a real pain point: attribution.
Who gave the data?
Who helped train the model?
Who deserves credit?
Who gets paid?
Who gets erased?
These questions are not clean. They are uncomfortable. And that is probably why most projects avoid them.
The thing is, crypto people have already lived through the ugly side of incentive systems. We know what happens when rewards are involved. We have seen airdrops get farmed into the ground. We have seen fake users flood testnets. We have seen communities act loyal until the claim page opens. We have seen “organic traction” turn out to be wallets chasing points.
So when OpenLedger talks about rewarding data contributors, my first reaction is not blind praise.
My first reaction is: okay, but how do you stop the garbage?
Because people will try to game it.
They always do.
If there is a reward for contributing data, some users will contribute useful data. Others will dump junk. Duplicate content. Low-effort material. Sybil accounts. Recycled noise. Anything that looks like activity from the outside.
That is the mess OpenLedger has to survive.
And it is a serious mess.
This is where the project becomes interesting, but also hard. Proof of Attribution sounds like the right direction, but AI attribution is not simple. A model does not learn like a person reading one paragraph and saying, “Thanks, this exact idea came from here.” It absorbs patterns. It mixes sources. It compresses information. It becomes very hard to say who contributed what in a way that feels fair.
So OpenLedger is not solving some easy little tracking problem.
It is walking into one of the most annoying parts of AI.
Maybe that is why I respect the attempt.
Not the hype around it. The attempt.
The idea of Datanets also makes sense to me because specialized data is probably where this has a better chance. I do not really believe every crypto AI project needs to fight OpenAI or Google or the giant labs directly. That usually sounds like fantasy. Those companies have money, talent, compute, distribution, and lawyers. Crypto has Telegram groups arguing about unlocks.
But focused data networks?
That feels more realistic.
A niche community building around a specific type of data. A model trained for a specific use case. Contributors getting tracked. Value not just disappearing into some closed machine. That is not some glamorous story, but it is closer to actual infrastructure.
And crypto needs more of that.
Less theatre.
More plumbing.
Still, OpenLedger has a hard road. It has to prove that people will contribute quality data, not just farm rewards. It has to prove that builders care enough to use the system. It has to prove that attribution can be trusted, even if it is not perfect. It has to prove that the token is connected to real usage, not just another reason for people to speculate during an AI cycle.
That last part matters.
Because there is a token, and once there is a token, everything changes.
People stop asking what the system does and start asking when it lists, when it pumps, when the next campaign starts, when the next reward drops. The project becomes a market object before it becomes useful infrastructure. That is the normal crypto disease.
OpenLedger is not immune to it.
No project is.
OPEN having a role in fees, rewards, and network activity gives it some logic. Fine. That is better than a token that only exists for governance theatre. But utility on paper is not enough. If the network does not create real demand, the token becomes another circular machine.
Rewards bring users.
Users create activity.
Activity creates hype.
Hype supports the token.
Then rewards slow down.
And suddenly everyone finds out what was real.
We have seen that movie too many times.
That is why I do not want to over-sell OpenLedger. The idea is strong enough without pretending it is guaranteed. It might take time. It might be messy. It might work only in certain niches first. It might struggle with quality control. It might attract more farmers than builders early on.
That would not surprise me.
Actually, I expect some of that.
But the project is still touching something important. AI has a value extraction problem. A lot of people contribute to the knowledge layer, but only a few platforms capture most of the upside. OpenLedger is trying to make that contribution layer visible and usable.
That is worth watching.
Not worshipping.
Watching.
Look, I do not need OpenLedger to become some giant world-changing thing for it to matter. Crypto people love making everything dramatic. Sometimes a project only needs to fix one ugly piece of infrastructure that everyone else keeps ignoring.
Data attribution is one of those ugly pieces.
Nobody wants to think about it when the model output looks clean. Nobody wants to ask where the value came from when the demo works. Nobody wants to deal with the boring accounting of contribution, ownership, and reward.
But eventually, that stuff matters.
Especially if AI keeps eating more of the internet.
The hard part for OpenLedger is trust. Not just trust in the chain. Trust in the process. Trust that contribution is measured fairly. Trust that the reward system does not become a farming game. Trust that the datasets are actually useful. Trust that builders are not just there for incentives. Trust that the whole thing is not another AI narrative wearing infrastructure clothing.
That is a lot of trust to earn.
And it will not be earned through slogans.
It will be earned through boring usage.
People contributing real data. Builders making models that actually work. Users paying because the output is useful. Communities staying after the hype cools down. Less noise. More proof.
That is the only version of OpenLedger that matters to me.
Maybe it gets there.
Maybe it does not.
The thing is, I would rather watch a project trying to solve a boring, real problem than another shiny AI token pretending a chatbot needs a coin. OpenLedger at least lives closer to the actual mess: data, attribution, incentives, contributors, and model value.
That is not clean.
That is not easy.
But it feels closer to reality.
And after enough crypto cycles, reality starts to matter more than the pitch.
@OpenLedger
#OpenLedger
$OPEN
104
#openledger $OPEN Exploring the future of decentralized AI with @OpenLedger 🔥
The vision behind OpenLedger is creating a smarter ecosystem where AI and blockchain work together seamlessly. As innovation keeps growing, $OPEN could become one of the most talked-about projects in Web3. Keeping this gem on my watchlist for the long term 👀🚀
#OpenLedger $OPEN
{future}(OPENUSDT)
#openledger $OPEN Exploring the future of decentralized AI with @OpenLedger 🔥
The vision behind OpenLedger is creating a smarter ecosystem where AI and blockchain work together seamlessly. As innovation keeps growing, $OPEN could become one of the most talked-about projects in Web3. Keeping this gem on my watchlist for the long term 👀🚀
#OpenLedger $OPEN
The vision behind OpenLedger is creating a smarter ecosystem where AI and blockchain work together seamlessly. As innovation keeps growing, $OPEN could become one of the most talked-about projects in Web3. Keeping this gem on my watchlist for the long term 👀🚀
#OpenLedger $OPEN
2
16
·
--
Bullish
Most projects treat exchange listings like a milestone.
Price pops. Volume spikes. Twitter celebrates.
Then two weeks later everyone moves on.
I've been thinking about @Openledger BitMart listing back in February. At the time the $OPEN price dropped 6% on listing day, which is unusual. Most listings pump.
The drop didn't bother me as much as what it revealed.
Exchange listings matter differently for infrastructure projects than they do for consumer tokens. A meme coin needs liquidity and retail access to survive. An infrastructure layer needs developer adoption, enterprise integrations, and protocol usage liquidity is almost secondary.
$OPEN getting listed on BitMart, MEXC, and other venues is necessary. But it's not the signal worth watching.
The signal worth watching is whether anyone is actually paying $OPEN to use the network. AI credits, datanet creation fees, attribution transactions, these are the numbers that tell you if the infrastructure is being used.
Not the order book depth. The fee revenue.
One of these metrics is easy to find. The other takes five minutes of on-chain research.
Guess which one most people are looking at.
#OpenLedger
{future}(OPENUSDT)
Most projects treat exchange listings like a milestone.
Price pops. Volume spikes. Twitter celebrates.
Then two weeks later everyone moves on.
I've been thinking about @OpenLedger BitMart listing back in February. At the time the $OPEN price dropped 6% on listing day, which is unusual. Most listings pump.
The drop didn't bother me as much as what it revealed.
Exchange listings matter differently for infrastructure projects than they do for consumer tokens. A meme coin needs liquidity and retail access to survive. An infrastructure layer needs developer adoption, enterprise integrations, and protocol usage liquidity is almost secondary.
$OPEN getting listed on BitMart, MEXC, and other venues is necessary. But it's not the signal worth watching.
The signal worth watching is whether anyone is actually paying $OPEN to use the network. AI credits, datanet creation fees, attribution transactions, these are the numbers that tell you if the infrastructure is being used.
Not the order book depth. The fee revenue.
One of these metrics is easy to find. The other takes five minutes of on-chain research.
Guess which one most people are looking at.
#OpenLedger
Price pops. Volume spikes. Twitter celebrates.
Then two weeks later everyone moves on.
I've been thinking about @OpenLedger BitMart listing back in February. At the time the $OPEN price dropped 6% on listing day, which is unusual. Most listings pump.
The drop didn't bother me as much as what it revealed.
Exchange listings matter differently for infrastructure projects than they do for consumer tokens. A meme coin needs liquidity and retail access to survive. An infrastructure layer needs developer adoption, enterprise integrations, and protocol usage liquidity is almost secondary.
$OPEN getting listed on BitMart, MEXC, and other venues is necessary. But it's not the signal worth watching.
The signal worth watching is whether anyone is actually paying $OPEN to use the network. AI credits, datanet creation fees, attribution transactions, these are the numbers that tell you if the infrastructure is being used.
Not the order book depth. The fee revenue.
One of these metrics is easy to find. The other takes five minutes of on-chain research.
Guess which one most people are looking at.
#OpenLedger
1
266

·
--
Something I noticed while working through a CreatorPad task for OpenLedger ($OPEN , #OpenLedger , @Openledger ) is how cleanly the project separates its infrastructure story from its user-facing reality. The pitch is a unified layer where AI computation, decentralized data, and token incentives flow into each other seamlessly — but what you actually touch during the task is closer to a staking and participation interface, with the AI infrastructure present mostly as context, not as something you interact with directly. The automation the name implies is not frictionless; it is conditional, gated behind a set of contribution behaviors that reward early, technically-oriented participants far more than general users. There is a design choice buried in that gap: the ecosystem works as promised for the people building it, and works as narrative for everyone else who arrives through the token. What stays with me is not criticism — it is the question of whether the two groups ever actually converge into the same product, or whether that convergence is always deferred to the next phase.
@Openledger
#OpenLedger
$OPEN
Something I noticed while working through a CreatorPad task for OpenLedger ($OPEN , #OpenLedger , @OpenLedger ) is how cleanly the project separates its infrastructure story from its user-facing reality. The pitch is a unified layer where AI computation, decentralized data, and token incentives flow into each other seamlessly — but what you actually touch during the task is closer to a staking and participation interface, with the AI infrastructure present mostly as context, not as something you interact with directly. The automation the name implies is not frictionless; it is conditional, gated behind a set of contribution behaviors that reward early, technically-oriented participants far more than general users. There is a design choice buried in that gap: the ecosystem works as promised for the people building it, and works as narrative for everyone else who arrives through the token. What stays with me is not criticism — it is the question of whether the two groups ever actually converge into the same product, or whether that convergence is always deferred to the next phase.
@OpenLedger
#OpenLedger
$OPEN
@OpenLedger
#OpenLedger
$OPEN
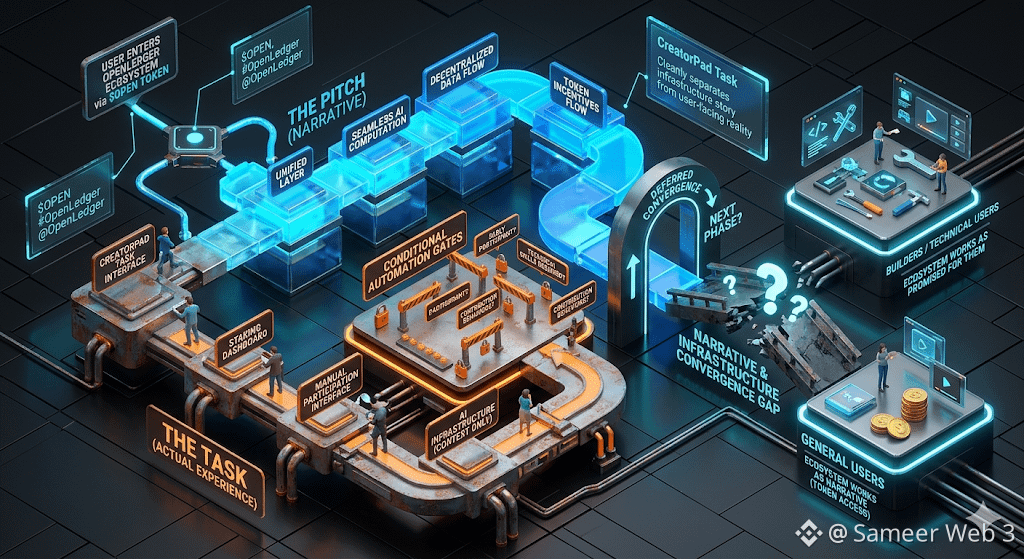
138
Log in to explore more content
Join global crypto users on Binance Square
⚡️ Get latest and useful information about crypto.
💬 Trusted by the world’s largest crypto exchange.
👍 Discover real insights from verified creators.
Email / Phone number
Trending Topics
1
#IsAnthropic’s$1.5TMarketCapJustified?
40,630 views
209 Discussing
2
#BTCBelow$62KAmidHikeFearsAndShiftToAnthropic
4,660 views
46 Discussing
3
#NvidiaBoardReportedlySplitOverHuang’sReturn
185,337 views
1,549 Discussing
4
#CanGTA6'sLaunchLiftTTWOShares?
146,594 views
1,112 Discussing
5
#LedgerProbesTamperedWalletsInBerlinAndDubai
9,537 views
134 Discussing
6
#13FInstitutionsBitcoinSpotETPHoldingsHitRecord
20,732 views
202 Discussing
7
#BTCRemainsUnderPressureAfterHawkishFOMCMinutes
353,970 views
2,422 Discussing
8
#StrategySTRCPreferredSlips3.65%Below$100Par
12,177 views
96 Discussing
9
#MASToUpgradeSGDTestnetToSGDigitalLedger
44,784 views
424 Discussing
10
#Solana2027RoadmapTargetsDoubleComputeCapacity
27,946 views
241 Discussing